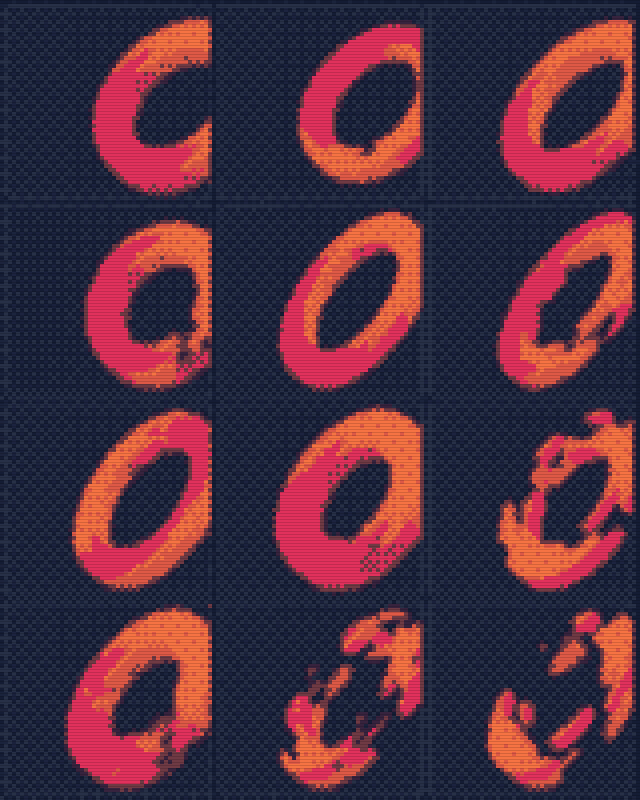
Models › gpt-oss family

openai Apache 2.0 out 15 months ago

117B parameters (4 of 128 experts per token), text in, text out, 128K tokens of context. 27 providers serve it from $0.030 per million input tokens.

Verified 2026-10-25 Rank #2 in LLMs · score 138.8 method v1 Sources 5 Downloads 30d 2.9M · #50 of 619 tracked

Changed this week: 1 new provider: Nscale.2026-10-23

What does it cost?$0.030/1M incheapest of 25DeepInfrabfloat162026-10-25
Can I use it?Apache 2.0Permissive; patent grantlicence file2026-10-24
Does it work?5/5probes · 168 tok/sfirst lookparasail2026-10-07
Do people use it?2.9Mdownloads, 30 days#50 of 619 we track · top 8%+22 likes, downloads −13% this week5,438 likesHugging Face2026-10-24

The ringer: four playful tests

A pelican steals a bicycle from a supermarket

as received● 4/4 on palette
SVG reply: a pelican steals a bicycle from a supermarket
Draw a pelican stealing a bicycle from a supermarket. Reply with one complete SVG document only, no prose and no code fences. Use viewBox="0 0 200 150" and a transparent background. Use only these colours for every fill and stroke: #06e0c0 #ffc298 #cd85f9 #f1f2f2.

Finish the dad joke

as received● 1 line · 9 words

Why did the open-weights model cross the road?

To get to the other side of the dataset.

Finish this dad joke. Reply with the punchline only, on one line, without quotes: Why did the open-weights model cross the road?

A parasailer, in ASCII

as received● 9×19 fits 12×32
        __/\\__        
       /      \       
      /  O O  \      
     /   ^    \     
    /__________\    
        |||          
        |||          
       /   \        
 ~~~ ~~~~~ ~~~ ~~~~  
Draw ASCII art of a parasailer over the sea. At most 12 lines and 32 columns. Reply with the art only: no code fences, no explanation.

Animate a bouncing ball

as received● 8 frames · 16×16
Make a 16x16 pixel sprite animation of a ball bouncing, 8 frames. Reply with JSON only, no code fences: {"palette": {"a": "#rrggbb", ...}, "fps": <number>, "frames": [[16 strings of 16 characters], ...]}. At most 4 palette colours with single-letter keys; "." means transparent; exactly 8 frames.
1 of 4 · swipe for more

The ringer: the same four playful tests for every model, replies shown as received and checked by code. A joke, not a benchmark; never ranked.4 of 4 pass · parasail-gpt-oss-120b on parasail · run 2026-10-09 · temperature 0 · cost $0.004 · 2026-10 thing: supermarket · all models →

Worth reading

Picked by rule from 44 tracked pieces: the lab's own post, the most shared, a field report, the latest.

Most discussed · 490 HN pts

GPT-OSS vs. Qwen3 and a detailed look how things evolved since GPT-2

OpenAI released gpt-oss-120b and gpt-oss-20b, their first open-weight models since GPT-2 in 2019.

  • A 2025 research paper confirms Dropout results in worse downstream performance in single-epoch regimes.
magazine.sebastianraschka.com 2025-08-10 490 HN pts · 97 comments 5.2k words about the gpt oss family family
Latest · 3 months ago

Show HN: ExpertCache – Run the Full GPT-OSS 120B (63GB) on a 16GB M1 Pro

ExpertCache is an experimental page-aware Metal runtime that exposes only selected expert ranges to Metal through page-aligned direct host-memory views to run oversized sparse mixture-of-experts checkpoints.

  • The 16 GiB M1 Pro path completed the seven-scenario 8K qualification in 8,249 seconds total.
  • The successful 16 GiB configuration explicitly disabled automatic fit and whole-file mmap prefetch.
github.com 2026-08-08 4 HN pts 1.3k words

25 best of 44 tracked

The 4 picks above, plus these 21. Top is the radar's score: discussion, source authority and the lab's own posts, fading with age.

  1. ArticleShow HN: Distilling DeepSeek into GPT-OSS doesn't transfer censorship. Try itctgt.ai · 2026-07-30 · 170 HN pts
  2. ArticleRunning GPT-OSS-120B at 500 tokens per second on Nvidia GPUsbaseten.co · 2025-08-07 · 247 HN pts
  3. ArticleIntroducing gpt-ossopenai.com · 2025-08-05 · 175 HN pts · official
  4. ArticleGPT-OSS Reinforcement Learningdocs.unsloth.ai · 2025-09-27 · 180 HN pts
  5. ArticleWhat GPT-OSS leaks about OpenAI's training datafi-le.net · 2025-10-05 · 348 HN pts
  6. DiscussionShow HN: I taught GPT-OSS-120B to see using Google Lens and OpenCVnews.ycombinator.com · 2026-02-11 · 43 HN pts
  7. DiscussionCurious about the training data of OpenAI's new GPT-OSS models? I was tootwitter.com · 2025-08-09
  8. PaperIs GPT-OSS Good? A Comprehensive Evaluation of OpenAI's ...arxiv.org · undated
  9. Articlegpt-oss-120b — Architecture, Evals & Inference Performance | InferenceXinferencex.semianalysis.com · undated
  10. ArticleIntroducing OpenAI gpt-oss (20b & 120b) - Fireworks AIfireworks.ai · undated
  11. ArticleVisualizing GPT-OSS-20B embeddingsmelonmars.github.io · 2025-08-17
  12. ArticleGPT-OSS 120B Runs at 3000 tokens/sec on Cerebrascerebras.ai · 2025-11-08
  13. ArticleGPT-OSS-Safeguardopenai.com · 2025-10-29 · official
  14. ArticleOpenAI GPT-OSS Model Card [pdf]cdn.openai.com · 2025-08-05 · official
  15. CodeLlama.cpp: Add GPT-OSSgithub.com · 2025-08-05
  16. CodeShow HN: BrowserOS -- browser agents with GPT-OSS, local llmsgithub.com · 2025-08-22
  17. ArticleUsing Codex CLI with GPT-OSS:120B on an Nvidia DGX Spark via Tailscaletil.simonwillison.net · 2025-11-07
  18. ArticleGPT-OSS-120B (high): API Provider Performance Benchmarkingartificialanalysis.ai · 2025-08-13
  19. CodeShow HN: Run gpt-oss-20b on 8GB GPUsgithub.com · 2025-09-03
  20. CodeOpenAI GPT-OSSgithub.com · 2025-08-05
  21. CodeShow HN: We let GPT OSS 120B write and run Python and ARC AGI 2 jumped 4xgithub.com · 2026-02-11

Where to run it

Live hosted endpoints, cheapest first, USD per million tokens. Ties break on output price, then provider name.

Prices for the same weights vary 12×

25 providers with a live price, from $0.030 to $0.35 per million input tokens; the median is $0.10. One dot per provider, cheapest in teal.

$0.010$0.10$1.00$10.00DeepInfra: $0.030 in / $0.14 out per 1M · observed 2026-10-25 · https://huggingface.co/api/models/openai/gpt-oss-120b?expand[]=inferenceProviderMappingNear AI: $0.030 in / $0.15 out per 1M · observed 2026-10-24 · https://openrouter.ai/openai/gpt-oss-120bVenice: $0.030 in / $0.15 out per 1M · observed 2026-10-24 · https://openrouter.ai/openai/gpt-oss-120bCoreWeave: $0.030 in / $0.17 out per 1M · observed 2026-10-24 · https://openrouter.ai/openai/gpt-oss-120bDekaLLM: $0.030 in / $0.18 out per 1M · observed 2026-10-24 · https://openrouter.ai/openai/gpt-oss-120bAkashML: $0.030 in / $0.19 out per 1M · observed 2026-10-24 · https://openrouter.ai/openai/gpt-oss-120bNovita: $0.050 in / $0.25 out per 1M · observed 2026-10-25 · https://huggingface.co/api/models/openai/gpt-oss-120b?expand[]=inferenceProviderMappingCrusoe: $0.050 in / $0.25 out per 1M · observed 2026-10-24 · https://openrouter.ai/openai/gpt-oss-120bMancer 2: $0.050 in / $0.25 out per 1M · observed 2026-10-24 · https://openrouter.ai/openai/gpt-oss-120bDigitalOcean: $0.060 in / $0.42 out per 1M · observed 2026-10-24 · https://openrouter.ai/openai/gpt-oss-120bOVHcloud: $0.090 in / $0.47 out per 1M · observed 2026-10-25 · https://huggingface.co/api/models/openai/gpt-oss-120b?expand[]=inferenceProviderMappingNscale: $0.10 in / $0.40 out per 1M · observed 2026-10-25 · https://huggingface.co/api/models/openai/gpt-oss-120b?expand[]=inferenceProviderMappingBaseten: $0.10 in / $0.50 out per 1M · observed 2026-10-25 · https://huggingface.co/api/models/openai/gpt-oss-120b?expand[]=inferenceProviderMappingParasail: $0.10 in / $0.75 out per 1M · observed 2026-10-24 · https://docs.parasail.io/parasail-docs/billing/pricingSambaNova: $0.14 in / $0.95 out per 1M · observed 2026-10-24 · https://openrouter.ai/openai/gpt-oss-120bGroq: $0.15 in / $0.75 out per 1M · observed 2026-10-25 · https://huggingface.co/api/models/openai/gpt-oss-120b?expand[]=inferenceProviderMappingTogether AI: $0.15 in / $0.60 out per 1M · observed 2026-10-25 · https://huggingface.co/api/models/openai/gpt-oss-120b?expand[]=inferenceProviderMappingFireworks AI: $0.15 in / $0.60 out per 1M · observed 2026-10-25 · https://huggingface.co/api/models/openai/gpt-oss-120b?expand[]=inferenceProviderMappingAmazon Bedrock: $0.15 in / $0.60 out per 1M · observed 2026-10-24 · https://openrouter.ai/openai/gpt-oss-120bNebius: $0.15 in / $0.60 out per 1M · observed 2026-10-24 · https://openrouter.ai/openai/gpt-oss-120bSiliconFlow: $0.15 in / $0.60 out per 1M · observed 2026-10-24 · https://openrouter.ai/openai/gpt-oss-120b+2Scaleway: $0.17 in / $0.68 out per 1M · observed 2026-10-25 · https://huggingface.co/api/models/openai/gpt-oss-120b?expand[]=inferenceProviderMappingCerebras: $0.35 in / $0.75 out per 1M · observed 2026-10-25 · https://huggingface.co/api/models/openai/gpt-oss-120b?expand[]=inferenceProviderMappingcheapest $0.030median $0.10
$0.010$0.10$1.00$10.00DeepInfra: $0.030 in / $0.14 out per 1M · observed 2026-10-25 · https://huggingface.co/api/models/openai/gpt-oss-120b?expand[]=inferenceProviderMappingNear AI: $0.030 in / $0.15 out per 1M · observed 2026-10-24 · https://openrouter.ai/openai/gpt-oss-120bVenice: $0.030 in / $0.15 out per 1M · observed 2026-10-24 · https://openrouter.ai/openai/gpt-oss-120bCoreWeave: $0.030 in / $0.17 out per 1M · observed 2026-10-24 · https://openrouter.ai/openai/gpt-oss-120bDekaLLM: $0.030 in / $0.18 out per 1M · observed 2026-10-24 · https://openrouter.ai/openai/gpt-oss-120bAkashML: $0.030 in / $0.19 out per 1M · observed 2026-10-24 · https://openrouter.ai/openai/gpt-oss-120bNovita: $0.050 in / $0.25 out per 1M · observed 2026-10-25 · https://huggingface.co/api/models/openai/gpt-oss-120b?expand[]=inferenceProviderMappingCrusoe: $0.050 in / $0.25 out per 1M · observed 2026-10-24 · https://openrouter.ai/openai/gpt-oss-120bMancer 2: $0.050 in / $0.25 out per 1M · observed 2026-10-24 · https://openrouter.ai/openai/gpt-oss-120bDigitalOcean: $0.060 in / $0.42 out per 1M · observed 2026-10-24 · https://openrouter.ai/openai/gpt-oss-120bOVHcloud: $0.090 in / $0.47 out per 1M · observed 2026-10-25 · https://huggingface.co/api/models/openai/gpt-oss-120b?expand[]=inferenceProviderMappingNscale: $0.10 in / $0.40 out per 1M · observed 2026-10-25 · https://huggingface.co/api/models/openai/gpt-oss-120b?expand[]=inferenceProviderMappingBaseten: $0.10 in / $0.50 out per 1M · observed 2026-10-25 · https://huggingface.co/api/models/openai/gpt-oss-120b?expand[]=inferenceProviderMappingParasail: $0.10 in / $0.75 out per 1M · observed 2026-10-24 · https://docs.parasail.io/parasail-docs/billing/pricingSambaNova: $0.14 in / $0.95 out per 1M · observed 2026-10-24 · https://openrouter.ai/openai/gpt-oss-120bGroq: $0.15 in / $0.75 out per 1M · observed 2026-10-25 · https://huggingface.co/api/models/openai/gpt-oss-120b?expand[]=inferenceProviderMappingTogether AI: $0.15 in / $0.60 out per 1M · observed 2026-10-25 · https://huggingface.co/api/models/openai/gpt-oss-120b?expand[]=inferenceProviderMappingFireworks AI: $0.15 in / $0.60 out per 1M · observed 2026-10-25 · https://huggingface.co/api/models/openai/gpt-oss-120b?expand[]=inferenceProviderMappingAmazon Bedrock: $0.15 in / $0.60 out per 1M · observed 2026-10-24 · https://openrouter.ai/openai/gpt-oss-120bNebius: $0.15 in / $0.60 out per 1M · observed 2026-10-24 · https://openrouter.ai/openai/gpt-oss-120bSiliconFlow: $0.15 in / $0.60 out per 1M · observed 2026-10-24 · https://openrouter.ai/openai/gpt-oss-120b+2Scaleway: $0.17 in / $0.68 out per 1M · observed 2026-10-25 · https://huggingface.co/api/models/openai/gpt-oss-120b?expand[]=inferenceProviderMappingCerebras: $0.35 in / $0.75 out per 1M · observed 2026-10-25 · https://huggingface.co/api/models/openai/gpt-oss-120b?expand[]=inferenceProviderMappingcheapest $0.030 · median $0.10 (white tick)
#Cheapest 5In /1MOut /1MContextQuantSeen
1 DeepInfra $0.030 $0.14 128K bfloat16 Oct 25
2 Near AI $0.030 $0.15 128K fp4 Oct 24
3 Venice $0.030 $0.15 125K int4 Oct 24
4 CoreWeave $0.030 $0.17 128K fp4 Oct 24
5 DekaLLM $0.030 $0.18 128K bf16 Oct 24

All 27 providers →

Where it's used

Hugging Face does not say who downloads a model or with what. These are the proxies: API providers listing it, quantized builds, fine-tunes/adapters/merges, and Spaces that load it.

Widely served (27 API providers); heavily run locally (134 quantized builds); a big base for builders (370 fine-tunes, adapters and merges).

  • As a service27AkashML, Amazon Bedrock, Baseten, Cerebras +23
  • On own hardware134quantized builds
  • Built on370124 fine-tunes · 245 adapters · 1 merges
  • In apps100+Hugging Face Spaces

Top Spaces running it: hadadxyz/ai ♥ 819 · ginipick/FLUXllama ♥ 561 · smolagents/ml-intern ♥ 423 · burtenshaw/karpathy-llm-council ♥ 292

Will it fit?

Weights only, an estimate: leave room for the KV cache. Method

Fits two 80 GB GPUs at INT4; too big for one

About 70 GB at INT4, 140 GB at FP8, 280 GB at BF16: weights only, so leave room for the KV cache. Every expert must be resident, so total parameters count.

16 GB card64 GB Mac2×80 GB8×80 GBINT4: about 70 GB of weights (estimate; KV cache and activations extra)INT470 GBFP8: about 140 GB of weights (estimate; KV cache and activations extra)FP8140 GBBF16: about 280 GB of weights (estimate; KV cache and activations extra)BF16280 GB

Estimate params × bytes per param × 1.2 · how we estimate

How it scores

Third-party measurements only; author-reported numbers stay in Reference, marked as such.

#6 of 13 on Aider Polyglot so far

41.8. Each tick is a model on this site with a measured Aider Polyglot row; author-reported numbers stay in Reference. Percent (pass_rate_2). edit_format=diff

deepseek-ai/DeepSeek-R1-0528: 71.4 · observed 2026-10-25 · https://aider.chat/docs/leaderboards/Qwen/Qwen3-235B-A22B: 59.6 · observed 2026-10-25 · https://aider.chat/docs/leaderboards/moonshotai/Kimi-K2-Instruct: 59.1 · observed 2026-10-25 · https://aider.chat/docs/leaderboards/deepseek-ai/DeepSeek-R1: 56.9 · observed 2026-10-25 · https://aider.chat/docs/leaderboards/deepseek-ai/DeepSeek-V3-0324: 55.1 · observed 2026-10-25 · https://aider.chat/docs/leaderboards/Qwen/Qwen3-32B: 40 · observed 2026-10-25 · https://aider.chat/docs/leaderboards/Qwen/QwQ-32B: 26.2 · observed 2026-10-25 · https://aider.chat/docs/leaderboards/Qwen/QwQ-32B: 20.9 · observed 2026-10-25 · https://aider.chat/docs/leaderboards/Qwen/Qwen2.5-Coder-32B-Instruct: 16.4 · observed 2026-10-25 · https://aider.chat/docs/leaderboards/meta-llama/Llama-4-Maverick-17B-128E-Instruct: 15.6 · observed 2026-10-25 · https://aider.chat/docs/leaderboards/Qwen/Qwen2.5-Coder-32B-Instruct: 8 · observed 2026-10-25 · https://aider.chat/docs/leaderboards/google/gemma-3-27b-it: 4.9 · observed 2026-10-25 · https://aider.chat/docs/leaderboards/010041.8 · #6 of 13

Source · leaderboard · 2025-08-06

Day-one receipts

The probe replies as received on 2026-10-07 from parasail, graded by code. Receipts, not a score.

Write a function● pass
def is_balanced(s: str) -> bool:
    pairs = {')': '(', ']': '[', '}': '{'}
    stack = []
    for ch in s:
        if ch in '([{':
            stack.append(ch)
        elif ch in ')]}':
            if not stack or stack[-1] != pairs[ch]:
                return False
            stack.pop()
    retu
Bracket-balance function passes 9 hidden asserts4.5 s
Needle at 128K● pass
amber-falcon-7731
Needle recall at ~128k input tokens (needle at 37%)6.2 s
Tool call● pass
{"city": "Lisbon", "unit": "c"}
Emits a correct function call (get_weather, city=Lisbon)0.7 s
Strict JSON● pass
{
  "name": "Foo-9B-Instruct",
  "license": "Apache-2.0",
  "parameters_b": 9.2,
  "context_tokens": 131072,
  "languages": ["English", "French", "German", "Japanese"]
}
Structured extraction to strict JSON (5 fields)2.3 s
Speed run● pass
{
  "providers": [
    {
      "provider": "parasail",
      "endpoint_model": "parasail-gpt-oss-120b",
      "source_url": "https://api.parasail.io/v1/chat/completions",
      "ttft_ms_median": 889,
      "ttft_any_ms_median": 589,
      "tokens_per_s_median": 101.5,
      "runs": [
        {
          "ttft_s": 0.889,
          "ttft_any_s": 0.589,
          "tokens_per_s": 129.8,
          "latency_s": 1.86,
          "tokens_out": 241,
          "reasoning_chars": 184,
          "finish": "stop"
        },
        {
          "ttft_s": 1.123,
          "ttft_any_s": 0.592,
          "tokens_per_s": 96.8,
          "latency_s": 2.55,
          "tokens_out": 247,
          "reasoning_chars": 197,
          "finish": "stop"
        },
        {
          "ttft_s": 0.875,
          "ttft_any_s": 0.575,
          "tokens_per_s": 101.5,
          "latency_s": 2.37,
          "tokens_out": 241,
          "reasoning_chars": 172,
          "finish": "stop"
        }
      ]
    }
  ],
  "note": "Single client, wall clock; tok/s counts every output token including hidden reasoning."
}
Three-tool errand● pass
{
  "calls": [
    {
      "name": "get_weather",
      "args": {
        "city": "Lisbon",
        "date": "2026-10-14"
      }
    },
    {
      "name": "check_calendar",
      "args": {
        "date": "2026-10-14"
      }
    },
    {
      "name": "book_table",
      "args": {
        "restaurant": "Cervejaria Ramiro",
        "date": "2026-10-14",
        "time": "19:30",
        "party_size": 2
      }
    }
  ],
  "checks": {
    "get_weather": true,
    "check_calendar": true,
    "book_table": true
  },
  "final": "The reservation at Cervejaria Ramiro for two people on Wednesday, 2026‑10‑14 at 19:30 has been confirmed. Your confirmation code is **TBL-4471**. Enjoy your dinner!",
  "fixture": "receipts.errand.v1"
}
calls in order · args 3/3 · confirmed · 2026-10-095.3 s

Every probe, with timings and cost →

The story so far

Weights, every dated article, and repo commits on one rail.

9 dated articles and 17 repo commits so far

Teal is the weights (2025-08-04), amber triangles are 9 dated articles (each links to it), grey ticks are repo commits.

What people built on it

504 derivatives on the Hub. Which build to run, by runtime: the most downloaded in each class.

504 derivatives on the Hub, led by 245 adapters

From the Hugging Face model tree; quantized builds in teal, fine-tunes, merges and adapters in greys.

134 quantized (Hugging Face model tree)124 fine-tunes (Hugging Face model tree)1 merge (Hugging Face model tree)245 adapters (Hugging Face model tree)134 quantized124 fine-tunes1 merge245 adapters

All variants →

Reference

Everything else, folded: the full tables, every source.

Benchmarks

2 rows

Benchmarks 2 rows

measured third-party leaderboard row (2)author-reported number from the model card or eval filesNo confidence intervals unless the source gave them; settings differ between rows, so compare within a benchmark, not across. Date = the benchmark's own date when it gives one, else when we read it.
BenchmarkValueSetting / notesReported byDate
measured Aider Polyglot · Write code with agents41.8 percent (pass_rate_2)edit_format=diffleaderboard2025-08-06
measured SWE-bench Verified · Write code with agents26 percent resolvedagent: mini-SWE-agentleaderboard2025-08-07

Use-case evidence

5 use cases

What it is good at 5 use cases

Labels are evidence, not verdicts: measured a third-party leaderboard row for this model; author-reported a number the model author published in the card or eval files; structural a deterministic signal from the name, config or chat template, or a decision-model estimate. Each chip links to its source. All use cases.

Facts

22 fields

Listed in LLMs · MoE

Facts

Pipeline tagtext-generation
Librarytransformers
ArchitecturesGptOssForCausalLM
Model typegpt_oss
Params by dtypeBF16: 2,167,371,072 · U8: 114,661,785,600
Size bandXXL
MoEyes
Experts128
Experts per token4
Context length131,072 (config.json max_position_embeddings)
PapersarXiv:2508.10925
LicenseApache 2.0 (apache-2.0)
Hub snapshot2026-10-25

Servability

vLLM · SGLang

Servability

vLLM: supported · GptOssForCausalLM · 7050ef881ff0835f6890a47db1859a24c65481d6SGLang: supported · GptOssForCausalLM · 773cb938fe9484a8f7e7e46fb1b1fe96412c59ed

vLLM registry (7050ef881ff0835f6890a47db1859a24c65481d6) · SGLang registry (773cb938fe9484a8f7e7e46fb1b1fe96412c59ed) · Matched by architecture class name against each project's registry on main; 'supported' means the architecture is registered, not that this checkpoint was tested.

Hardware fit

3 estimates

Hardware fit ESTIMATE

Weights-only memory for gpt-oss-120b: params × bytes/param × 1.2 overhead. KV cache and activations are extra. How this is computed.

BF16 (2 bytes/param)280 GB · Multi-GPU node (<640 GB)
FP8 (1 byte/param)140 GB · Multi-GPU node (<640 GB)
INT4 (0.5 bytes/param)70 GB · Single high-end GPU (<80 GB)

Weights only (params × bytes/param × 1.2 overhead); KV cache and activations extra. MoE: all experts must be resident, so total parameters count.

First look, every probe

6 probes

First look measured

A fixed probe set run against a live API endpoint: the same questions for every model, answers graded by code, nothing judged by a model. Latencies are single-request wall clock from one client location, not a benchmark.

via parasail parasail-gpt-oss-120b 5/5 probes pass first visible token 0.8 s end-to-end 168 tok/s (median of 3)
ProbeResultLatencyReply (truncated)
Self-description info 1.3 s I am ChatGPT, a large language model built on OpenAI’s GPT‑4 architecture and created by OpenAI. My training data includes information up to June 2024.
Tool call pass 0.7 s {"city": "Lisbon", "unit": "c"}
Strict JSON pass 2.3 s { "name": "Foo-9B-Instruct", "license": "Apache-2.0", "parameters_b": 9.2, "context_tokens": 131072, "languages": ["English", "French", "German", "Japanese"] }
Code (hidden tests) pass 4.5 s def is_balanced(s: str) -> bool: pairs = {')': '(', ']': '[', '}': '{'} stack = [] for ch in s: if ch in '([{': stack.append(ch) elif ch in ')]}': if not stack or stack[-1] != pairs[ch]: return False stack.pop() retu
Multi-step arithmetic pass 1.2 s 16
Needle recall at 128k tokens pass 6.2 s amber-falcon-7731

Probe set firstlook.v1 · observed 2026-10-07 20:03 UTC · endpoint · provider docs · cost of this run $0.01

All variants

40 variants

Lineage

Original release (shipped quantized by the lab) Family: openai/gpt-oss 504 derivatives on the Hub

quantized: 134finetune: 124adapter: 245merge: 1

Top variants (40 shown, ranked by downloads)

Relation
Quant
Size
40 rows
Variant Relation Quant Params Band License Author Likes Downloads
ggml-org/gpt-oss-120b-GGUF quantized GGUF — — apache-2.0 ggml-org 81 2.9M
unsloth/gpt-oss-120b-GGUF quantized GGUF — — apache-2.0 unsloth 298 2.1M
lmstudio-community/gpt-oss-120b-MLX-8bit quantized MLX 117B XXL apache-2.0 lmstudio-community 15 1.1M
unsloth/gpt-oss-120b quantized — 117B XXL apache-2.0 unsloth 23 684.7k
unsloth/gpt-oss-120b-BF16 finetune -BF16 117B XXL apache-2.0 unsloth 9 615k
lmstudio-community/gpt-oss-120b-GGUF quantized GGUF — — apache-2.0 lmstudio-community 19 404.5k
unsloth/gpt-oss-120b-unsloth-bnb-4bit quantized -bnb 117B XXL apache-2.0 unsloth 20 294.5k
openai/gpt-oss-safeguard-120b finetune — 117B XXL apache-2.0 openai 120 238.2k
nvidia/gpt-oss-120b-Eagle3-short-context finetune — 787M S other nvidia 22 238.2k
nvidia/gpt-oss-120b-Eagle3-long-context finetune — 215M S other nvidia 91 161.3k
mlx-community/gpt-oss-120b-MXFP4-Q8 quantized MXFP4 117B XXL apache-2.0 mlx-community 21 131.7k
amd/gpt-oss-120b-w-mxfp4-a-fp8 quantized mxfp4 59.5B XL apache-2.0 amd 10 122.7k
bartowski/openai_gpt-oss-120b-GGUF quantized GGUF — — — bartowski 13 122.2k
HauhauCS/GPTOSS-120B-Uncensored-HauhauCS-Aggressive quantized GGUF — — apache-2.0 HauhauCS 95 107k
nvidia/gpt-oss-120b-Eagle3-v3 finetune — 787M S other nvidia 16 99.6k
tiny-random/gpt-oss-bf16 finetune -bf16 6.85M S — tiny-random 1 97.8k
twhitworth/gpt-oss-120b-awq-w4a16 finetune awq 117B XXL apache-2.0 twhitworth 24 81.8k
DavidAU/Openai_gpt-oss-120b-NEO-Imatrix-GGUF quantized Imatrix — — apache-2.0 DavidAU 26 59.2k
RedHatAI/gpt-oss-120b quantized — 120B XXL apache-2.0 RedHatAI 6 51.1k
yujiepan/gpt-oss-tiny-random finetune — 6.85M S — yujiepan 2 39.6k
DevQuasar/openai.gpt-oss-120b-GGUF quantized GGUF — — — DevQuasar 2 23.5k
mlx-community/gpt-oss-120b-MXFP4-Q4 quantized MXFP4 117B XXL apache-2.0 mlx-community 7 20.2k
tiny-random/gpt-oss-mxfp4 quantized mxfp4 6.87M S — tiny-random 0 20.2k
ArliAI/gpt-oss-120b-Derestricted finetune — 117B XXL apache-2.0 ArliAI 87 15.7k
gabriellarson/gpt-oss-120b-GGUF quantized GGUF — — apache-2.0 gabriellarson 5 17.1k
bartowski/openai_gpt-oss-120b-GGUF-MXFP4-Experimental quantized GGUF — — — bartowski 12 16.5k
NexVeridian/gpt-oss-120b-3bit quantized — 117B XXL apache-2.0 NexVeridian 6 11.5k
nvidia/gpt-oss-120b-Eagle3-throughput finetune — 762M S other nvidia 38 9.8k
giladgd/gpt-oss-120b-GGUF quantized GGUF — — apache-2.0 giladgd 1 11.4k
FreeSEED-AI/gpt-oss-120b-mandarin-thinking finetune — 117B XXL apache-2.0 FreeSEED-AI 51 8.2k
cloudyu/GPT-OSS-120B-2experts-MLX-q4-Claude-4.6-Opus-Reasoning-Distilled adapter MLX 117B XXL other cloudyu 9 9.7k
ZERO-POINT-AI/undermaintenance__118b-gpt-faulty quantized GGUF 117B XXL apache-2.0 ZERO-POINT-AI 6 9k
MultiverseComputingCAI/HyperNova-60B quantized — 58.7B XL apache-2.0 MultiverseComputingCAI 62 5.8k
furiosa-ai/gpt-oss-120b quantized — 117B XXL apache-2.0 furiosa-ai 0 8.7k
tiny-random/gpt-oss finetune — 6.85M S — tiny-random 2 7.8k
yujiepan/gpt-oss-tiny-random-mxfp4 quantized mxfp4 6.87M S — yujiepan 0 6.1k
mlx-community/gpt-oss-120b-mxfp4-bf16 quantized mxfp4 117B XXL apache-2.0 mlx-community 3 5.9k
dealignai/GPT-OSS-120B-MLX-CRACK quantized MLX 117B XXL apache-2.0 dealignai 5 5.1k
exalandru/GPT-OSS-Coder-GGUF finetune GGUF — — apache-2.0 exalandru 2 5k
michaelwaves/amoral-gpt-oss-120b-bfloat16 finetune — 117B XXL apache-2.0 michaelwaves 1 4.4k

Repository changelog

17 commits
changed in the last 7 daysNew providers: 2026-10-23all changes

Repository changelog 17 commits

DateCommitSHA
2025-08-26 Update README.md b5c939d
2025-08-13 Configure `<|call|>` as an EOS token (#105) 8b193b0
2025-08-13 Update README 5c98b88
2025-08-08 Update chat_template.jinja (#85) bc75b44
2025-08-08 Update README.md ef8a86a
2025-08-08 Update README.md 88fa8c2
2025-08-08 Update README.md 34a49b3
2025-08-07 Chat template cleanups + latest fixes (#76) 988e56b
2025-08-06 Remove chat_template.json (#58) eabf0c5
2025-08-05 Update README 4c0fa49
2025-08-05 Update LICENSE a9cc02b
2025-08-05 Update vLLM command a040b35
2025-08-05 Add model card acd9ca9
2025-08-05 Upload folder using huggingface_hub f39accd
2025-08-05 Upload folder using huggingface_hub ed282e6
2025-08-04 Upload folder using huggingface_hub 8c05803
2025-08-04 initial commit 62af5b1

All providers

27 providers · 27 endpoints

Where to run 27 providers · 27 endpoints

Hosted endpoints observed for gpt-oss-120b, sorted by input price (USD per million tokens). Each row names its observer and date; prices change daily, so check the source before quoting. Cheapest observed input price: $0.03/M.

ProviderModel refContextQuant$/M in$/M outtok/sTTFTToolsStatusObserved
DeepInfra
hf, deepinfra, openrouter
openai/gpt-oss-120b 128K bfloat16 $0.03 $0.14 76.4 228 ms yes live 2026-10-25
Near AI
openrouter
openai/gpt-oss-120b 128K fp4 $0.03 $0.15 — — yes live 2026-10-24
Venice
openrouter
openai/gpt-oss-120b 125K int4 $0.03 $0.15 — — yes live 2026-10-24
CoreWeave
openrouter
openai/gpt-oss-120b 128K fp4 $0.03 $0.17 — — yes live 2026-10-24
DekaLLM
openrouter
openai/gpt-oss-120b 128K bf16 $0.03 $0.18 — — yes live 2026-10-24
AkashML
openrouter
openai/gpt-oss-120b 128K bf16 $0.03 $0.19 — — yes live 2026-10-24
Novita
hf, openrouter
openai/gpt-oss-120b 128K fp4 $0.05 $0.25 119.3 4648 ms yes live 2026-10-25
Crusoe
openrouter
openai/gpt-oss-120b 128K bf16 $0.05 $0.25 — — yes live 2026-10-24
Mancer 2
openrouter
openai/gpt-oss-120b 128K fp8 $0.05 $0.25 — — yes live 2026-10-24
DigitalOcean
openrouter
openai/gpt-oss-120b 125K unknown $0.06 $0.42 — — — live 2026-10-24
OVHcloud
hf
gpt-oss-120b 128K — $0.09 $0.47 37.5 927 ms yes live 2026-10-25
Google
openrouter
openai/gpt-oss-120b 128K unknown $0.09 $0.36 — — — status -5 2026-10-24
Nscale
hf
openai/gpt-oss-120b 128K — $0.10 $0.40 122.8 348 ms yes live 2026-10-25
Baseten
hf, openrouter
openai/gpt-oss-120b 125K fp4 $0.10 $0.50 259.1 172 ms yes live 2026-10-25
Parasail
parasail, openrouter
parasail-gpt-oss-120b 128K fp4 $0.10 $0.75 — — yes serverless 2026-10-24
SambaNova
openrouter
openai/gpt-oss-120b 128K unknown $0.14 $0.95 — — yes live 2026-10-24
Groq
hf, openrouter
openai/gpt-oss-120b 128K unknown $0.15 $0.75 406.9 250 ms yes live 2026-10-25
Together AI
hf, openrouter
openai/gpt-oss-120b 128K unknown $0.15 $0.60 159 536 ms yes live 2026-10-25
Fireworks AI
hf
accounts/fireworks/models/gpt-oss-120b 128K — $0.15 $0.60 172.3 432 ms yes live 2026-10-25
Amazon Bedrock
openrouter
openai/gpt-oss-120b 128K unknown $0.15 $0.60 — — — live 2026-10-24
Nebius
openrouter
openai/gpt-oss-120b 128K fp4 $0.15 $0.60 — — yes live 2026-10-24
SiliconFlow
openrouter
openai/gpt-oss-120b 128K fp8 $0.15 $0.60 — — — live 2026-10-24
Phala
openrouter
openai/gpt-oss-120b 128K unknown $0.15 $0.60 — — yes live 2026-10-24
Mara
openrouter
openai/gpt-oss-120b 128K unknown $0.15 $0.75 — — yes live 2026-10-24
Scaleway
hf
gpt-oss-120b — — $0.17 $0.68 158.1 256 ms yes live 2026-10-25
Cerebras
hf, openrouter
gpt-oss-120b 128K fp16 $0.35 $0.75 178.6 4964 ms yes live 2026-10-25
Featherless
hf
openai/gpt-oss-120b — — — — — — — live 2026-10-25

Articles and coverage

44 pieces

Ranked by source signals (HN, Lobsters, authority domains, official posts) and recency. Summaries are generated from a stored copy of the article text; every sentence cites a span of that text, and nothing is shown that failed the citation check.

Official3

openai.com2025-08-05officialauthorityHN front pageabout the gpt oss familyHN 175 pts · 11 comments
deploymentsafety.openai.comofficialauthority415 words
docs.unsloth.ai2025-09-27authorityHN front pageabout the gpt oss familyHN 180 pts · 43 comments1,473 words
Unsloth enables reinforcement learning training for OpenAI gpt-oss using GRPO, offering 3x faster inference and 50% lower VRAM usage compared to other implementations. Flash Attention 3 causes incorrect training losses due to lack of backward pass support for attention sinks, so Unsloth Flex Attention provides O(N) memory usage instead of O(N^2) for naive attention. Reward hacking countermeasures include inspecting imports, wiping caches, and restricting global variable access to ensure genuine task performance.written, reviewed, cited
  • Unsloth achieves ~21 tokens/s for gpt-oss RL inference by rewriting code from Transformers since vLLM lacks compatibility.
  • Training gpt-oss-20b with GRPO is possible on 15GB VRAM using embedding offloading which reduces usage by 1GB.

Analysis5

ctgt.ai2026-07-30HN front pageabout the gpt oss familyHN 170 pts · 73 comments2,582 words
A study using DeepSeek V4 Flash as a teacher and GPT-OSS-120B as a student found that political censorship did not transfer during financial reasoning distillation. The LineageEval framework evaluated 304 prompts, revealing the distilled model scored 83.61% on FinanceReasoning at an 8,000-token budget. This approach costs $0.00025939 per query, significantly lower than competing models, while avoiding the teacher's selective avoidance of China-related content.written, reviewed, cited
  • The distilled 120B model scores 83.61% on FinanceReasoning, outperforming Kimi K3 at 81.93% and Inkling at 65.13%.
  • The 120B model serves from a single H100 or A100 with base weights in their native MXFP4 at roughly 63 GB.
  • At an expanded 100,000-token budget, the self-distilled 120B remains stable while Kimi K3 falls to 81.93% and Inkling to 65.13%.
github.com2026-08-08authorityHN 4 pts · 0 comments1,334 words
ExpertCache is an experimental page-aware Metal runtime that exposes only selected expert ranges to Metal through page-aligned direct host-memory views to run oversized sparse mixture-of-experts checkpoints. It targets the 63,387,346,208-byte GPT-OSS 120B MXFP4 GGUF checkpoint, achieving a 70% prefill speedup from 5.75 to 9.80 tokens/second on a 64 GiB M1 Max system. The approach avoids binding or copying the complete expert tensor into the active Metal working set.written, reviewed, cited
  • The 16 GiB M1 Pro path completed the seven-scenario 8K qualification in 8,249 seconds total.
  • The successful 16 GiB configuration explicitly disabled automatic fit and whole-file mmap prefetch.
  • ExpertCache-authored code is Apache-2.0, while the manuscript source and compiled paper are separately licensed CC BY 4.0.
magazine.sebastianraschka.com2025-08-10authorityHN front pageabout the gpt oss familyHN 490 pts · 97 comments5,195 words
OpenAI released gpt-oss-120b and gpt-oss-20b, their first open-weight models since GPT-2 in 2019. The 20B model can run on a consumer GPU with up to 16 GB of RAM, and the 120B model can run on a single H100 with 80 GB of RAM or newer hardware. The models utilize MXFP4 optimization to fit onto single GPUs.written, reviewed, cited
  • A 2025 research paper confirms Dropout results in worse downstream performance in single-epoch regimes.
baseten.co2025-08-07authorityHN front pageHN 247 pts · 175 comments857 words
Baseten optimized GPT OSS 120B on NVIDIA GPUs to achieve SOTA latency and throughput at launch. The team reached speeds of over 650 tokens per second on Artificial Analysis and higher on OpenRouter. They selected Tensor Parallelism for better latency on Hopper and Blackwell architectures while using the TensorRT-LLM MoE Backend for Blackwell. Speculative decoding with Eagle is also being added to further improve performance.written, reviewed, cited
  • Optimized deployments parallelize the model across 4 or 8 GPUs for improved performance and throughput.
  • Tensor Parallelism offered better latency, while Expert Parallelism offered better system throughput.
  • The TensorRT-LLM MoE Backend adds improved CUDA kernels that outperform the previous Triton backend.
fi-le.net2025-10-05HN front pageabout the gpt oss familyHN 348 pts · 82 comments3,352 words

Community2

news.ycombinator.com2026-02-11HN 43 pts · 31 comments1,569 words
old.reddit.com2025-08-11HN front pageHN 248 pts · 79 comments
All coverage tracked for this model (44) — append-only, nothing is ever removed
TitleSourcePublishedFirst seenSignals
gpt-oss-120b & gpt-oss-20b Model Card - OpenAI Deployment Safety Hubdeploymentsafety.openai.com official—2026-10-07exa
Is GPT-OSS Good? A Comprehensive Evaluation of OpenAI's ...arxiv.org—2026-10-07exa
gpt-oss-120b — Architecture, Evals & Inference Performance | InferenceXinferencex.semianalysis.com—2026-10-07exa
Introducing OpenAI gpt-oss (20b & 120b) - Fireworks AIfireworks.ai—2026-10-07exa
gpt-oss-120b Coding Evaluation: New Top Open-Source Modeleval.16x.engineer—2026-10-07exa
OpenAI's GPT-OSS-120B and GPT-OSS-20B Review - Kingy AIkingy.ai—2026-10-07exa
Show HN: ExpertCache – Run the Full GPT-OSS 120B (63GB) on a 16GB M1 Progithub.com2026-08-082026-10-07hn
Show HN: Distilling DeepSeek into GPT-OSS doesn't transfer censorship. Try itctgt.ai2026-07-302026-10-07hn
Show HN: We let GPT OSS 120B write and run Python and ARC AGI 2 jumped 4xgithub.com2026-02-112026-10-07hn
Show HN: I taught GPT-OSS-120B to see using Google Lens and OpenCVnews.ycombinator.com2026-02-112026-10-07hn
GPT-OSS 120B Runs at 3000 tokens/sec on Cerebrascerebras.ai2025-11-082026-10-07hn
Using Codex CLI with GPT-OSS:120B on an Nvidia DGX Spark via Tailscaletil.simonwillison.net2025-11-072026-10-07hn
gpt-oss-safeguard: A new milestone for open source safety infrastructureroost.tools2025-10-292026-10-07hn
GPT-OSS-Safeguardopenai.com official2025-10-292026-10-07hn
Compiler optimizations for 5.8ms GPT-OSS-120B inference (not on GPUs)furiosa.ai2025-10-172026-10-07hn
What GPT-OSS leaks about OpenAI's training datafi-le.net2025-10-052026-10-07hn
GPT-OSS Reinforcement Learningdocs.unsloth.ai2025-09-272026-10-07hn
Show HN: Run gpt-oss-20b on 8GB GPUsgithub.com2025-09-032026-10-07hn
Show HN: BrowserOS -- browser agents with GPT-OSS, local llmsgithub.com2025-08-222026-10-07hn
Visualizing GPT-OSS-20B embeddingsmelonmars.github.io2025-08-172026-10-07hn
GPT-OSS-120B (high): API Provider Performance Benchmarkingartificialanalysis.ai2025-08-132026-10-07hn
GPT-OSS Reasoning and Any-LLM: Nuances of OpenAI API Compatibilityblog.mozilla.ai2025-08-122026-10-07hn
GPT-OSS-120B runs on just 8GB VRAM & 64GB+ system RAMold.reddit.com2025-08-112026-10-07hn
How Benchmaxxed is GPT-OSS-120B?cmart.blog2025-08-112026-10-07hn
GPT-OSS vs. Qwen3 and a detailed look how things evolved since GPT-2magazine.sebastianraschka.com2025-08-102026-10-07hn, exa
OpenAI GPT-OSS models use MXFP4 to cut inference coststheregister.com2025-08-102026-10-07hn
OpenAI’s Open-Weight Models: A Technical Deep Dive into the gpt-oss-120b and gpt-oss-20b Models | by Shubham | Mediumshubh7.medium.com2025-08-102026-10-07exa
Curious about the training data of OpenAI's new GPT-OSS models? I was tootwitter.com2025-08-092026-10-07hn
Gptoss120B – OpenAI Open Source Large Language Model GPT-OSS-120B Official Sitegptoss120b.app2025-08-092026-10-07hn
Telnyx adds GPT-5 and Groq GPT-OSS-120B to Voice AI Agentsnews.ycombinator.com2025-08-082026-10-07hn
How to Run Your Own OpenAI GPT OSS Server for Fun and Profitnorthcodie.blogspot.com2025-08-082026-10-07hn
AI medical diagnosis example with GPT-OSS 120B chain of thoughtgithub.com2025-08-072026-10-07hn
Running GPT-OSS-120B at 500 tokens per second on Nvidia GPUsbaseten.co2025-08-072026-10-07hn
GPT-OSS 120B Writes a Lisp in Go Fastelite-ai-assisted-coding.dev2025-08-062026-10-07hn
OpenAI's GPT-OSS models benchmarks worse than DeepSeek R1 and Qwen3 235Bxcancel.com2025-08-062026-10-07hn
GPT-OSS 120B bad at producing linguistically correct German texttwitter.com2025-08-062026-10-07hn
Cerebras now supports OpenAI GPT-OSS-120B at 3k Tokens Per SECcerebras.ai2025-08-062026-10-07hn
A first look at GPT-OSS-120B's coding abilityblog.brokk.ai2025-08-052026-10-07hn
GPT-OSS-120B Lisp interpreter in Gogist.github.com2025-08-052026-10-07hn
GPT-OSS is a big dealtwitter.com2025-08-052026-10-07hn
OpenAI GPT-OSSgithub.com2025-08-052026-10-07hn
OpenAI GPT-OSS Model Card [pdf]cdn.openai.com official2025-08-052026-10-07hn
Introducing gpt-ossopenai.com official2025-08-052026-10-07hn, exa
Llama.cpp: Add GPT-OSSgithub.com2025-08-052026-10-07hn

Papers

1 paper

Papers 1

arXiv links found in the model card and its tags. "Peer-reviewed" is shown only with evidence: a published venue in OpenAlex (measured) or the authors' own journal reference on arXiv (reported).

Similar models

3 models

Similar models

  • GLM-4.5-Air · 110B
    same size band (XXL), also MoE, same task (text-generation), fewer providers, permissive license
  • Laguna-S-2.1 · 118B
    same size band (XXL), also MoE, same task (text-generation), fewer providers
  • Ling-3.0-flash · 127B
    same size band (XXL), also MoE, same task (text-generation), fewer providers, permissive license

Sources

5 sources

Sources

Hub snapshot: 2026-10-25 · HF API: 2026-10-24 21:31 UTC · Providers: 2026-10-24 21:44 UTC · Articles: 2026-10-24 21:45 UTC · Summary: 2026-10-07 14:59 UTC · Last verified 2026-10-25

Follow gpt-oss-120b

Watch this model

Email alerts are not open yet; the feeds above are the same data. See feeds for the item schema.