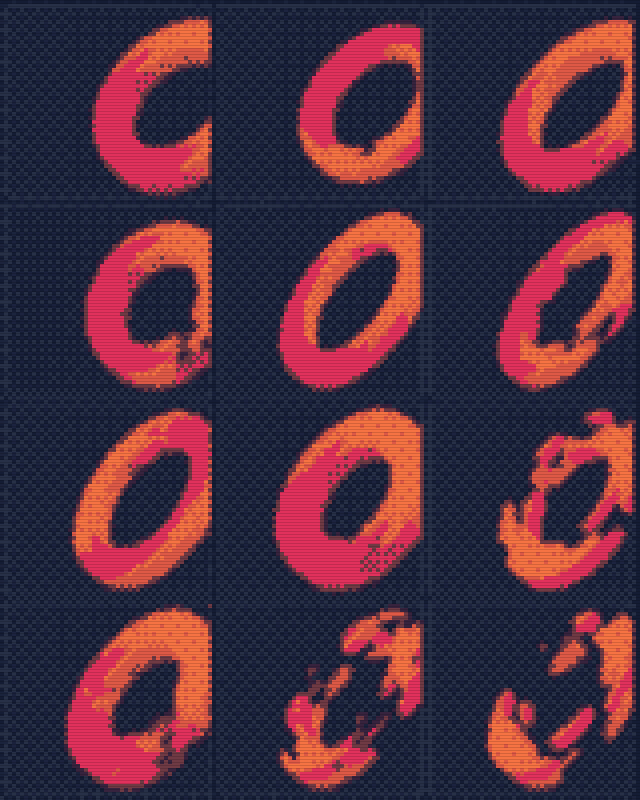Draw a pelican stealing a bicycle from a supermarket. Reply with one complete SVG document only, no prose and no code fences. Use viewBox="0 0 200 150" and a transparent background. Use only these colours for every fill and stroke: #06e0c0 #ffc298 #cd85f9 #f1f2f2.
Finish the dad joke
as received● 1 line · 10 words
Why did the open-weights model cross the road?
To get to the other side of the loss function
Finish this dad joke. Reply with the punchline only, on one line, without quotes: Why did the open-weights model cross the road?
Draw ASCII art of a parasailer over the sea. At most 12 lines and 32 columns. Reply with the art only: no code fences, no explanation.
Animate a bouncing ball
as received✕ 8 frames · bad grid
No playable frames in the reply.
Make a 16x16 pixel sprite animation of a ball bouncing, 8 frames. Reply with JSON only, no code fences: {"palette": {"a": "#rrggbb", ...}, "fps": <number>, "frames": [[16 strings of 16 characters], ...]}. At most 4 palette colours with single-letter keys; "." means transparent; exactly 8 frames.
1 of 4 · swipe for more →
The ringer: the same four playful tests for every model, replies shown as received and checked by code. A joke, not a benchmark; never ranked.3 of 4 pass · parasail-llama-33-70b-fp8 on parasail · run 2026-10-09 · temperature 0 · cost $0.001 · 2026-10 thing: supermarket · all models →
Worth reading
Picked by rule from 17 tracked pieces: the lab's own post, the most shared, a field report, the latest.
Hugging Face does not say who downloads a model or with what. These are the proxies: API providers listing it, quantized builds, fine-tunes/adapters/merges, and Spaces that load it.
Widely served (12 API providers); heavily run locally (170 quantized builds); a big base for builders (1,182 fine-tunes, adapters and merges).
As a service12AkashML, Cloudflare, CoreWeave, DeepInfra +8
Everything else, folded: the full tables, every source.
Benchmarks
1 row
Benchmarks 1 row
measured third-party leaderboard row (1)author-reported number from the model card or eval filesNo confidence intervals unless the source gave them; settings differ between rows, so compare within a benchmark, not across. Date = the benchmark's own date when it gives one, else when we read it.
Labels are evidence, not verdicts: measured a third-party leaderboard row for this model; author-reported a number the model author published in the card or eval files; structural a deterministic signal from the name, config or chat template, or a decision-model estimate. Each chip links to its source. All use cases.
Hosted endpoints observed for Llama-3.3-70B-Instruct, sorted by input price (USD per million tokens). Each row names its observer and date; prices change daily, so check the source before quoting. Cheapest observed input price: $0.10/M.
Ranked by source signals (HN, Lobsters, authority domains, official posts) and recency. Summaries are generated from a stored copy of the article text; every sentence cites a span of that text, and nothing is shown that failed the citation check.
goodfire.ai2024-12-23HN front pageHN 201 pts · 51 comments1,758 words
Goodfire released sparse autoencoders for Llama 3.3 70B, the most capable openly available model with interpretability tooling. The team created a UMAP 1 visualization of features and removed approximately 30% and 3.5% of features in their Llama 3.1 8B and Llama 3.3 70B SAEs respectively. Steering evaluations use a centiClaude scale where a strength of 0.4 begins pirate speech while factuality degrades by strength 1.written, reviewed, cited
Special formatting tokens often have large magnitudes, causing their SAE features to appear as isolated points away from central clusters.
Repeated features like the knowledge cutoff date may be memorized by the SAE and base model, altering their representation in latent space.
Feature steering benefits from narrower, sparser SAEs in the middle layers, whereas classification tasks likely benefit from broader SAEs early or late.
Meta released Llama 3.3 70B Instruct on December 6, 2024, as a dense, text-only model with 70B parameters and a 128k context window. The model matches Llama 3.1 70B on MMLU with an 86.0 score while beating the 405B variant on IFEval (92.1 vs 88.6) and MATH (77.0 vs 73.8). It uses Grouped-Query Attention and supports BF16, 8-bit, and 4-bit quantization via bitsandbytes.written, reviewed, cited
The Hugging Face repository lists 71B parameters for the checkpoint, differing from Meta's stated 70B count.
A separate Meta-granted license is required for licensees exceeding 700 million monthly active users as of the release date.
Llama 3.3 70B Instruct does not report scores for SWE-bench Verified, Codeforces, or τ-bench in its official model card.
Llama 3.3 Instruct 70B scores 8 on the Artificial Analysis Intelligence Index, placing it above average among comparable models with a median of 7. The model costs $0.71 per 1M input tokens and $0.72 per 1M output tokens, which is expensive compared to the median input price of $0.45.generated, cited
zlvox.com2026-07-20about the Llama 3.3 familyHN 2 pts · 0 comments582 words
The tool uses Groq Llama 3.3 70B to rewrite text with varied sentence lengths and natural imperfections. Users can process up to 5,000 characters per request without daily limits or signup requirements.generated, cited
github.com2025-04-26authorityHN 6 pts · 0 comments432 words
The distributed-llama repository runs Llama 3.3 70B Instruct Q40 on four NVIDIA RTX 3060 12 GB cards costing ~$1516. The embedding layer loads into RAM using --gpu-segments, requiring 13724387 kB of memory. This setup achieves 7.29 tok / s for evaluation and 3.35 tok / s for prediction.written, reviewed, cited
All coverage tracked for this model (17) — append-only, nothing is ever removed
arXiv links found in the model card and its tags. "Peer-reviewed" is shown only with evidence: a published venue in OpenAlex (measured) or the authors' own journal reference on arXiv (reported).