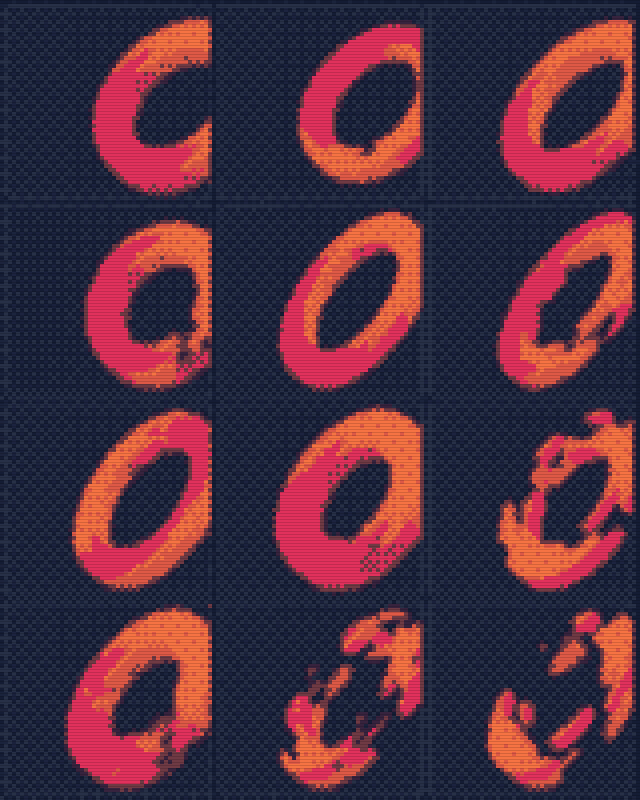Models › Llama-3.2 family

Llama-3.2-3B-Instruct

meta-llama Llama 3.2 Community License out 2 years ago

3.21B parameters, text in, text out, 128K tokens of context. 3 providers serve it from $0.050 per million input tokens.

Verified 2026-10-25 Rank #16 in LLMs · score 120.2 method v1 Sources 5 Downloads 30d 1.1M · #103 of 619 tracked

Changed this week: 2 new quantized builds on the Hub (542 in all).2026-10-24

Can I run it?1.9GB at INT4Estimatefits a 16 GB cardmethodCommunity: Llama 3.2 3B Review: Best Local LLM Under 5 GB? | BestLLMfor →
What does it cost?$0.050/1M incheapest of 2Parasailbf162026-10-24
Can I use it?Llama 3.2 Community LicenseAs 3.1; EU multimodal restriction in the textlicence file2026-10-24
Does it work?21.95on BFCL#26 of 28 measuredleaderboard2026-10-25
Do people use it?1.1Mdownloads, 30 days#103 of 619 we track · top 17%+66 likes, downloads −8% this week2,868 likesHugging Face2026-10-24

The ringer: four playful tests

A pelican steals a bicycle from a supermarket

as received✕ no SVG

No drawable SVG in the reply.

Draw a pelican stealing a bicycle from a supermarket. Reply with one complete SVG document only, no prose and no code fences. Use viewBox="0 0 200 150" and a transparent background. Use only these colours for every fill and stroke: #06e0c0 #ffc298 #cd85f9 #f1f2f2.

Finish the dad joke

as received✕ 1 line · 15 words

Why did the open-weights model cross the road?

To get to the other side, but it was a little "light" on its feet.

Finish this dad joke. Reply with the punchline only, on one line, without quotes: Why did the open-weights model cross the road?

A parasailer, in ASCII

as received✕ 13×18 over 12×32
___________
|           |
|  _______  |
| /        \ |
|/________\|
|           |
|  _______  |
| |       | |
| |  PARASAILER  |
| |       | |
| |_______| |
|           |
|___________|
Draw ASCII art of a parasailer over the sea. At most 12 lines and 32 columns. Reply with the art only: no code fences, no explanation.

Animate a bouncing ball

as received✕ not JSON

No playable frames in the reply.

Make a 16x16 pixel sprite animation of a ball bouncing, 8 frames. Reply with JSON only, no code fences: {"palette": {"a": "#rrggbb", ...}, "fps": <number>, "frames": [[16 strings of 16 characters], ...]}. At most 4 palette colours with single-letter keys; "." means transparent; exactly 8 frames.
1 of 4 · swipe for more

The ringer: the same four playful tests for every model, replies shown as received and checked by code. A joke, not a benchmark; never ranked.0 of 4 pass · parasail-llama-32-3b-instruct on parasail · run 2026-10-09 · temperature 0 · cost $0.011 · 2026-10 thing: supermarket · all models →

Worth reading

Picked by rule from 34 tracked pieces: the lab's own post, the most shared, a field report, the latest.

Latest · 2 years ago

I Self-Hosted Llama 3.2 with Coolify on My Home Server

A guide details self-hosting Llama 3.2 on a home server using Coolify and Ollama.

  • Anyone with physical access can read your data if you avoid LVM or disk encryption for smoother reboots.
  • Cloudflare provides free SSL certificates only for wildcard domains at the top level, not on subdomains.
geek.sg 2024-10-16 221 HN pts · 90 comments 2.3k words about the Llama 3.2 family family

25 best of 34 tracked

The 3 picks above, plus these 22. Top is the radar's score: discussion, source authority and the lab's own posts, fading with age.

  1. ArticleLlama 3.2: Revolutionizing edge AI and vision with open, customizable modelsai.meta.com · 2024-09-25 · 924 HN pts · official
  2. ArticleLlama 3.2: Revolutionizing edge AI and vision with open ...ai.meta.com · undated · official
  3. ArticleLlama 3.2 released: Multimodal, 1B to 90B sizesllama.com · 2024-09-25 · 89 HN pts · official
  4. CodeShow HN: MinLlama – Llama 3.2 inference in ~100 lines of NumPygithub.com · 2026-06-23 · 2 HN pts
  5. ArticleOllama 0.4 is released with support for Meta's Llama 3.2 Vision models locallyollama.com · 2024-11-06 · 182 HN pts
  6. ArticleLlama 3.2 Instruct 3B Intelligence, Performance & Price Analysisartificialanalysis.ai · undated
  7. ArticleLlama can now see and run on your device – welcome Llama 3.2huggingface.co · 2024-09-25 · 26 HN pts
  8. ArticleDownload Llama 3.2 1B, 3B, 11B, 90Bllama.com · 2024-09-25 · official
  9. ArticleShow HN: Llama 3.2 3B and Keiro Research achieves 85% on SimpleQAkeirolabs.cloud · 2026-03-07
  10. ArticleVerbatim AI – on-device transcription (Whisper) + summaries (Llama 3.2)apps.apple.com · 2026-04-21
  11. CodeLlama 3.2 Releasegithub.com · 2024-09-25
  12. ArticleLoad Llama-3.2 WebGPU in the browser from a local foldersimonwillison.net · 2025-09-09
  13. ArticleRWKV-7 beats Llama 3.2 with 3x fewer training tokens and formally exceeds TC^0ai.gopubby.com · 2026-02-23
  14. CodePydanticAI using Ollama (llama3.2) running locallygithub.com · 2024-12-06
  15. CodeShow HN: Recall – open-source local file organizer using Llama 3.2 and Ollamagithub.com · 2025-12-10
  16. CodeImplementing the Llama 3.2 1B and 3B Architectures from Scratchgithub.com · 2024-10-05
  17. CodeShow HN: MLX.zig – Llama 3.2 in Ziggithub.com · 2025-03-14
  18. ArticleOpen Source wireframe to app powered by Llama 3.2 Visionnapkins.dev · 2024-09-25
  19. ArticleShow HN: Finetune Llama 3.2 Vision in a Colabcolab.research.google.com · 2024-11-21
  20. DiscussionLlama 3.2: Lightweight models for edge devicestwitter.com · 2024-09-25
  21. ArticleLlama 3.2 3B Review: Best Local LLM Under 5 GB? | BestLLMforbestllmfor.com · 2026-05-28
  22. DiscussionLlama 3.2 1B and 3B on-device modelstwitter.com · 2024-09-25

Where to run it

Live hosted endpoints, cheapest first, USD per million tokens. Ties break on output price, then provider name.

2 providers from $0.050

2 providers with a live price, from $0.050 to $0.051 per million input tokens; the median is $0.050. One dot per provider, cheapest in teal.

$0.010$0.10$1.00$10.00Parasail: $0.050 in / $0.33 out per 1M · observed 2026-10-24 · https://docs.parasail.io/parasail-docs/billing/pricingCloudflare: $0.051 in / $0.34 out per 1M · observed 2026-10-24 · https://openrouter.ai/meta-llama/llama-3.2-3b-instructcheapest $0.050median $0.050
$0.010$0.10$1.00$10.00Parasail: $0.050 in / $0.33 out per 1M · observed 2026-10-24 · https://docs.parasail.io/parasail-docs/billing/pricingCloudflare: $0.051 in / $0.34 out per 1M · observed 2026-10-24 · https://openrouter.ai/meta-llama/llama-3.2-3b-instructcheapest $0.050 · median $0.050 (white tick)
#Cheapest 3In /1MOut /1MContextQuantSeen
1 Parasail $0.050 $0.33 128K bf16 Oct 24
2 Cloudflare $0.051 $0.34 78K unknown Oct 24
3 Featherless — — — — Oct 25

All 3 providers →

Where it's used

Hugging Face does not say who downloads a model or with what. These are the proxies: API providers listing it, quantized builds, fine-tunes/adapters/merges, and Spaces that load it.

Served by 3 API providers; heavily run locally (542 quantized builds); a big base for builders (2,939 fine-tunes, adapters and merges).

  • As a service3Cloudflare, Featherless, Parasail
  • On own hardware542quantized builds
  • Built on2,9392,038 fine-tunes · 872 adapters · 29 merges
  • In apps100+Hugging Face Spaces

Top Spaces running it: pliny-the-prompter/obliteratus ♥ 621 · cvachet/pdf-chatbot ♥ 382 · jupyter-agent/jupyter-agent ♥ 321 · baconnier/prompt-plus-plus ♥ 246

Will it fit?

Weights only, an estimate: leave room for the KV cache. Method

Fits a 16 GB card at INT4

About 1.9 GB at INT4, 3.9 GB at FP8, 7.7 GB at BF16: weights only, so leave room for the KV cache.

16 GB card64 GB Mac2×80 GB8×80 GBINT4: about 1.9 GB of weights (estimate; KV cache and activations extra)INT41.9 GBFP8: about 3.9 GB of weights (estimate; KV cache and activations extra)FP83.9 GBBF16: about 7.7 GB of weights (estimate; KV cache and activations extra)BF167.7 GB

Estimate params × bytes per param × 1.2 · how we estimate

How it scores

Third-party measurements only; author-reported numbers stay in Reference, marked as such.

#26 of 28 on BFCL so far

21.95. Each tick is a model on this site with a measured BFCL row; author-reported numbers stay in Reference. Percent (overall accuracy). FC

zai-org/GLM-4.6: 72.38 · observed 2026-10-25 · https://gorilla.cs.berkeley.edu/leaderboard.htmlmoonshotai/Kimi-K2-Instruct: 59.06 · observed 2026-10-25 · https://gorilla.cs.berkeley.edu/leaderboard.htmldeepseek-ai/DeepSeek-V3.2-Exp: 54.12 · observed 2026-10-25 · https://gorilla.cs.berkeley.edu/leaderboard.htmlQwen/Qwen3-235B-A22B-Instruct-2507: 52.15 · observed 2026-10-25 · https://gorilla.cs.berkeley.edu/leaderboard.htmlQwen/Qwen3-32B: 48.71 · observed 2026-10-25 · https://gorilla.cs.berkeley.edu/leaderboard.htmlQwen/Qwen3-235B-A22B-Instruct-2507: 47.99 · observed 2026-10-25 · https://gorilla.cs.berkeley.edu/leaderboard.htmlQwen/Qwen3-32B: 46.78 · observed 2026-10-25 · https://gorilla.cs.berkeley.edu/leaderboard.htmlSalesforce/Llama-xLAM-2-8b-fc-r: 46.68 · observed 2026-10-25 · https://gorilla.cs.berkeley.edu/leaderboard.htmlQwen/Qwen3-8B: 42.57 · observed 2026-10-25 · https://gorilla.cs.berkeley.edu/leaderboard.htmlQwen/Qwen3-30B-A3B-Instruct-2507: 41.39 · observed 2026-10-25 · https://gorilla.cs.berkeley.edu/leaderboard.htmlQwen/Qwen3-14B: 41.03 · observed 2026-10-25 · https://gorilla.cs.berkeley.edu/leaderboard.htmlQwen/Qwen3-8B: 40.43 · observed 2026-10-25 · https://gorilla.cs.berkeley.edu/leaderboard.htmlQwen/Qwen3-14B: 37.77 · observed 2026-10-25 · https://gorilla.cs.berkeley.edu/leaderboard.htmlQwen/Qwen3-30B-A3B-Instruct-2507: 36.7 · observed 2026-10-25 · https://gorilla.cs.berkeley.edu/leaderboard.htmlQwen/Qwen3-4B-Instruct-2507: 35.68 · observed 2026-10-25 · https://gorilla.cs.berkeley.edu/leaderboard.htmlQwen/Qwen3-4B-Instruct-2507: 35.52 · observed 2026-10-25 · https://gorilla.cs.berkeley.edu/leaderboard.htmlmeta-llama/Llama-3.3-70B-Instruct: 31.9 · observed 2026-10-25 · https://gorilla.cs.berkeley.edu/leaderboard.htmlgoogle/gemma-3-12b-it: 30.43 · observed 2026-10-25 · https://gorilla.cs.berkeley.edu/leaderboard.htmlgoogle/gemma-3-27b-it: 29.47 · observed 2026-10-25 · https://gorilla.cs.berkeley.edu/leaderboard.htmlmicrosoft/phi-4: 28.79 · observed 2026-10-25 · https://gorilla.cs.berkeley.edu/leaderboard.htmlQwen/Qwen3-1.7B: 28.41 · observed 2026-10-25 · https://gorilla.cs.berkeley.edu/leaderboard.htmlmeta-llama/Llama-4-Scout-17B-16E-Instruct: 28.13 · observed 2026-10-25 · https://gorilla.cs.berkeley.edu/leaderboard.htmlmeta-llama/Llama-3.1-8B-Instruct: 25.83 · observed 2026-10-25 · https://gorilla.cs.berkeley.edu/leaderboard.htmlQwen/Qwen3-0.6B: 23.93 · observed 2026-10-25 · https://gorilla.cs.berkeley.edu/leaderboard.htmlQwen/Qwen3-0.6B: 22.38 · observed 2026-10-25 · https://gorilla.cs.berkeley.edu/leaderboard.htmlgoogle/gemma-3-4b-it: 19.62 · observed 2026-10-25 · https://gorilla.cs.berkeley.edu/leaderboard.htmlgoogle/gemma-3-1b-it: 7.17 · observed 2026-10-25 · https://gorilla.cs.berkeley.edu/leaderboard.html010021.95 · #26 of 28

Source · leaderboard · 2026-10-25

Day-one receipts

Claim-matched tests, graded by code. Receipts, not a score.

Speed run● pass
{
  "providers": [
    {
      "provider": "parasail",
      "endpoint_model": "parasail-llama-32-3b-instruct",
      "source_url": "https://api.parasail.io/v1/chat/completions",
      "ttft_ms_median": 456,
      "ttft_any_ms_median": 456,
      "tokens_per_s_median": 200.8,
      "runs": [
        {
          "ttft_s": 0.66,
          "ttft_any_s": 0.66,
          "tokens_per_s": 159.9,
          "latency_s": 1.15,
          "tokens_out": 184,
          "reasoning_chars": 0,
          "finish": "stop"
        },
        {
          "ttft_s": 0.441,
          "ttft_any_s": 0.441,
          "tokens_per_s": 200.9,
          "latency_s": 0.92,
          "tokens_out": 184,
          "reasoning_chars": 0,
          "finish": "stop"
        },
        {
          "ttft_s": 0.456,
          "ttft_any_s": 0.456,
          "tokens_per_s": 200.8,
          "latency_s": 0.92,
          "tokens_out": 184,
          "reasoning_chars": 0,
          "finish": "stop"
        }
      ]
    }
  ],
  "note": "Single client, wall clock; tok/s counts every output token including hidden reasoning."
}

The story so far

Weights, every dated article, and repo commits on one rail.

8 dated articles and 0 repo commits so far

Teal is the weights (2024-09-18), amber triangles are 8 dated articles (each links to it).

What people built on it

3,481 derivatives on the Hub. Which build to run, by runtime: the most downloaded in each class.

3,481 derivatives on the Hub, most of them fine-tunes

From the Hugging Face model tree; quantized builds in teal, fine-tunes, merges and adapters in greys.

542 quantized (Hugging Face model tree)2,038 fine-tunes (Hugging Face model tree)29 merges (Hugging Face model tree)872 adapters (Hugging Face model tree)542 quantized2,038 fine-tunes29 merges872 adapters

All variants →

Reference

Everything else, folded: the full tables, every source.

Benchmarks

1 row

Benchmarks 1 row

measured third-party leaderboard row (1)author-reported number from the model card or eval filesNo confidence intervals unless the source gave them; settings differ between rows, so compare within a benchmark, not across. Date = the benchmark's own date when it gives one, else when we read it.
BenchmarkValueSetting / notesReported byDate
measured BFCL · Call tools and APIs21.95 percent (overall accuracy)FC
5 sub-scores
  • Non-Live AST Acc: 82.67
  • Live Acc: 58.33
  • Multi Turn Acc: 4
  • Web Search Acc: 1
  • Memory Acc: 6.24
leaderboard2026-10-25

Use-case evidence

3 use cases

What it is good at 3 use cases

Labels are evidence, not verdicts: measured a third-party leaderboard row for this model; author-reported a number the model author published in the card or eval files; structural a deterministic signal from the name, config or chat template, or a decision-model estimate. Each chip links to its source. All use cases.

Facts

19 fields

Listed in LLMs

Facts

Pipeline tagtext-generation
Librarytransformers
ArchitecturesLlamaForCausalLM
Model typellama
Params by dtypeBF16: 3,212,749,824
Size bandM
MoEno
Context length131,072 (provider listing)
Gatedmanual
PapersarXiv:2204.05149, arXiv:2405.16406
LicenseLlama 3.2 Community License (llama3.2)
Hub snapshot2026-10-25

Servability

vLLM · SGLang

Servability

vLLM: supported · LlamaForCausalLM · 7050ef881ff0835f6890a47db1859a24c65481d6SGLang: supported · LlamaForCausalLM · 773cb938fe9484a8f7e7e46fb1b1fe96412c59ed

vLLM registry (7050ef881ff0835f6890a47db1859a24c65481d6) · SGLang registry (773cb938fe9484a8f7e7e46fb1b1fe96412c59ed) · Matched by architecture class name against each project's registry on main; 'supported' means the architecture is registered, not that this checkpoint was tested.

Hardware fit

3 estimates

Hardware fit ESTIMATE

Weights-only memory for Llama-3.2-3B-Instruct: params × bytes/param × 1.2 overhead. KV cache and activations are extra. How this is computed.

BF16 (2 bytes/param)7.7 GB · Single GPU (<24 GB)
FP8 (1 byte/param)3.9 GB · Edge (<4 GB)
INT4 (0.5 bytes/param)1.9 GB · Edge (<4 GB)

Weights only (params × bytes/param × 1.2 overhead); KV cache and activations extra.

All variants

40 variants

Lineage

Original model Family: meta-llama/Llama-3.2 3,481 derivatives on the Hub

quantized: 542finetune: 2,038merge: 29adapter: 872

Top variants (40 shown, ranked by downloads)

Relation
Quant
40 rows
Variant Relation Quant Params Band License Author Likes Downloads
MaziyarPanahi/Llama-3.2-3B-Instruct-GGUF quantized GGUF — — — MaziyarPanahi 15 10M
bartowski/Llama-3.2-3B-Instruct-GGUF quantized GGUF — — llama3.2 bartowski 251 4.9M
unsloth/Llama-3.2-3B-Instruct finetune — 3.21B M llama3.2 unsloth 99 4.3M
inference-net/Schematron-3B finetune — 3.21B M llama3.2 inference-net 345 3.5M
unsloth/Llama-3.2-3B-Instruct-unsloth-bnb-4bit quantized -bnb 3.30B M llama3.2 unsloth 11 2.4M
unsloth/Llama-3.2-3B-Instruct-bnb-4bit quantized -bnb 3.30B M llama3.2 unsloth 37 2.1M
unsloth/Llama-3.2-3B-Instruct-GGUF quantized GGUF — — llama3.2 unsloth 89 1.1M
mlx-community/Llama-3.2-3B-Instruct finetune — 3.21B M llama3.2 mlx-community 10 998.6k
RedHatAI/Llama-3.2-3B-Instruct-FP8-dynamic quantized -FP8 3.61B M llama3.2 RedHatAI 3 941.7k
lmstudio-community/Llama-3.2-3B-Instruct-GGUF quantized GGUF — — llama3.2 lmstudio-community 48 835.8k
RedHatAI/Llama-3.2-3B-Instruct-FP8 quantized -FP8 3.61B M llama3.2 RedHatAI 6 532.1k
hugging-quants/Llama-3.2-3B-Instruct-Q4_K_M-GGUF quantized GGUF — — — hugging-quants 49 472.8k
hugging-quants/Llama-3.2-3B-Instruct-Q8_0-GGUF quantized Q8_0 — — — hugging-quants 53 306.3k
SanctumAI/Llama-3.2-3B-Instruct-GGUF quantized GGUF — — llama3.2 SanctumAI 2 233.5k
X-iZhang/libra-v1.0-3b merge — 3.25B M apache-2.0 X-iZhang 2 196.2k
unsloth/Llama-3.2-3B-unsloth-bnb-4bit quantized -bnb 3.30B M llama3.2 unsloth 4 195.4k
canopylabs/orpheus-3b-0.1-pretrained finetune — 3.78B M apache-2.0 canopylabs 175 167k
mlc-ai/Llama-3.2-3B-Instruct-q4f32_1-MLC quantized — — — — mlc-ai 2 142.8k
acon96/Home-Llama-3.2-3B finetune GGUF 3.21B M other acon96 18 136.5k
QuantFactory/Llama-3.2-3B-Instruct-abliterated-GGUF quantized GGUF — — llama3.2 QuantFactory 36 125.5k
mlc-ai/Llama-3.2-3B-Instruct-q4f16_0-MLC quantized — — — — mlc-ai 2 120.9k
mlc-ai/Llama-3.2-3B-Instruct-q4f16_1-MLC quantized — — — — mlc-ai 5 101.5k
second-state/Llama-3.2-3B-Instruct-GGUF quantized GGUF — — llama3.2 second-state 4 78.4k
huihui-ai/Llama-3.2-3B-Instruct-abliterated finetune — 3.61B M llama3.2 huihui-ai 104 73k
radheneev/NetrAI-L3 finetune — 3.21B M llama3 radheneev 3 71.7k
RedHatAI/Llama-3.2-3B-Instruct-quantized.w8a8 quantized -quant 3.61B M llama3.2 RedHatAI 1 68.8k
uzlm/alloma-3B-Instruct finetune — 3.21B M llama3.2 uzlm 6 68k
HKUSTAudio/Llasa-3B finetune — 4.01B M cc-by-nc-4.0 HKUSTAudio 531 37k
QuantFactory/Llama-Sentient-3.2-3B-Instruct-GGUF quantized GGUF — — creativeml-openrail-m QuantFactory 2 49.6k
QuantFactory/VersatiLlama-Llama-3.2-3B-Instruct-Abliterated-GGUF quantized GGUF — — cc-by-4.0 QuantFactory 6 49.2k
QuantFactory/Llama3.2-3B-Enigma-GGUF quantized GGUF — — llama3.2 QuantFactory 4 41.1k
QuantFactory/Llama3.2-3B-Esper2-GGUF quantized GGUF — — llama3.2 QuantFactory 3 38.6k
espressor/meta-llama.Llama-3.2-3B-Instruct_W4A16 quantized — 3.63B M — espressor 0 37.9k
canopylabs/3b-de-pretrain-research_release finetune — 3.78B M llama3.2 canopylabs 14 29.9k
Skywork/Skywork-Reward-V2-Llama-3.2-3B finetune — 3.21B M llama3.2 Skywork 5 28.3k
QuantFactory/Llama-3.2-Taiwan-Legal-3B-Instruct-GGUF quantized GGUF — — llama3.2 QuantFactory 11 25.1k
legraphista/Llama-3.2-3B-Instruct-IMat-GGUF quantized GGUF — — llama3.2 legraphista 2 25.3k
ValiantLabs/Llama3.2-3B-ShiningValiant2 finetune — 3.21B M llama3.2 ValiantLabs 6 25.1k
CarrotAI/Llama-3.2-Rabbit-Ko-3B-Instruct finetune — 3.21B M llama3.2 CarrotAI 11 19.8k
suayptalha/DeepSeek-R1-Distill-Llama-3B finetune — 3.21B M llama3.2 suayptalha 16 19.1k

Repository changelog

1 change
changed in the last 7 daysOther: 2026-10-24all changes

All providers

3 providers · 3 endpoints

Where to run 3 providers · 3 endpoints

Hosted endpoints observed for Llama-3.2-3B-Instruct, sorted by input price (USD per million tokens). Each row names its observer and date; prices change daily, so check the source before quoting. Cheapest observed input price: $0.05/M.

ProviderModel refContextQuant$/M in$/M outtok/sTTFTToolsStatusObserved
Parasail
parasail, openrouter
parasail-llama-32-3b-instruct 128K bf16 $0.05 $0.33 — — — serverless 2026-10-24
Cloudflare
openrouter
meta-llama/llama-3.2-3b-instruct 78K unknown $0.05 $0.34 — — — live 2026-10-24
Featherless
hf
meta-llama/Llama-3.2-3B-Instruct — — — — — — — live 2026-10-25

Articles and coverage

34 pieces

Ranked by source signals (HN, Lobsters, authority domains, official posts) and recency. Summaries are generated from a stored copy of the article text; every sentence cites a span of that text, and nothing is shown that failed the citation check.

Official3

ai.meta.com2024-09-25officialauthorityHN front pageabout the Llama 3.2 familyHN 924 pts · 328 comments2,460 words
Meta releases Llama 3.2, featuring small and medium-sized vision LLMs (11B and 90B) alongside lightweight text-only models (1B and 3B) designed for edge and mobile devices. The 11B and 90B models serve as drop-in replacements for their corresponding text model equivalents while the 1B and 3B models support a context length of 128K tokens and are enabled on day one for Qualcomm and MediaTek hardware. Both pre-trained and aligned vision models are available for fine-tuning using torchtune and local deployment via torchchat, with weights based on BFloat16 numerics.written, reviewed, cited
  • The 11B and 90B vision models require an entirely new model architecture that supports image reasoning.
  • Developers can keep all text-only capabilities intact because the adapter training intentionally did not update the language-model parameters.
  • The 1B and 3B models are created by using structured pruning in a single shot manner from the Llama 3.1 8B.
ai.meta.comofficialauthorityabout the Llama 3.2 family2,460 words
Meta releases Llama 3.2, featuring small and medium-sized vision LLMs (11B and 90B) alongside lightweight text-only models (1B and 3B) designed for edge and mobile devices. The 1B and 3B models support a context length of 128K tokens and are enabled on day one for Qualcomm and MediaTek hardware, optimized for Arm processors. Both pre-trained and aligned vision models serve as drop-in replacements for their corresponding text model equivalents.written, reviewed, cited
  • The 11B and 90B vision models require an entirely new model architecture that supports image reasoning.
  • Developers can keep all text-only capabilities intact because the adapter training intentionally did not update the language-model parameters.
llama.com2024-09-25officialauthorityabout the Llama 3.2 familyHN 89 pts · 19 comments42 words

Analysis7

github.com2024-11-21authorityHN front pageabout the Llama 3.2 familyHN 579 pts · 99 comments5,768 words
The project trained a Sparse Autoencoder on 6.5 Billion activations from Llama 3.2-3B layer 23 over 10 epochs. Data capture processed 25 million sentences totaling 4TB of raw activation data compressed to 3.2TB.generated, cited
geek.sg2024-10-16HN front pageabout the Llama 3.2 familyHN 221 pts · 90 comments2,289 words
A guide details self-hosting Llama 3.2 on a home server using Coolify and Ollama. The author achieved a 10x reduction in inference time by enabling GPU acceleration on an NVIDIA GeForce RTX 2060 using the CUDA toolkit and nvidia-container-toolkit. The setup involves installing Ubuntu 24, configuring Cloudflare Tunnels, and managing CUDA toolkits.written, reviewed, cited
  • Anyone with physical access can read your data if you avoid LVM or disk encryption for smoother reboots.
  • Cloudflare provides free SSL certificates only for wildcard domains at the top level, not on subdomains.
  • The Ollama service initially runs on the CPU until the NVIDIA Container Toolkit is installed and configured.
github.com2026-06-23authorityabout the Llama 3.2 familyHN 2 pts · 0 comments196 words
A minimal implementation of Llama 3.2 Instruct inference runs in ~100 lines of pure Numpy code. The project supports Python ≥ 3.10 and includes backends for PyTorch and Jax alongside the primary Numpy version. Ingredients in Llama 3.2 include RoPE with the Llama-3 frequency scaling, GQA, RMSNorm, SwiGLU MLP, and a shared unembedding / embedding matrix.written, reviewed, cited
ollama.com2024-11-06HN front pageabout the Llama 3.2 familyHN 182 pts · 25 comments202 words
artificialanalysis.aiauthorityabout the Llama 3.2 family735 words
huggingface.co2024-09-25authorityabout the Llama 3.2 familyHN 26 pts · 1 comments3,434 words
bilawal.net2025-09-01HN 31 pts · 8 comments
All coverage tracked for this model (34) — append-only, nothing is ever removed
TitleSourcePublishedFirst seenSignals
Llama 3.2: Revolutionizing edge AI and vision with open ...ai.meta.com official—2026-10-07exa
Llama 3.2 Instruct 3B Intelligence, Performance & Price Analysisartificialanalysis.ai—2026-10-07exa
Meta: Llama 3.2 3B Instruct - AI Model Details & Benchmarksbenchable.ai—2026-10-07exa
Llama 3.2 3B Instruct – 128k context, open weights | LLM Referencellmreference.com—2026-10-07exa
LLaMA 3.2 Instruct: Adaptation and Analysisemergentmind.com—2026-10-07exa
Llama 3.2 3B Instruct: benchmarks, pricing & context — ModelCap #217modelcap.ai—2026-10-07exa
Llama 3.2 3B Instruct — local inference guiderunlocalai.co—2026-10-07exa
https://blog.ahmadwkhan.com/llama-3-2-a-deep-diveblog.ahmadwkhan.com—2026-10-07exa
Show HN: MinLlama – Llama 3.2 inference in ~100 lines of NumPygithub.com2026-06-232026-10-07hn
Llama 3.2 3B Review: Best Local LLM Under 5 GB? | BestLLMforbestllmfor.com2026-05-282026-10-07exa
Verbatim AI – on-device transcription (Whisper) + summaries (Llama 3.2)apps.apple.com2026-04-212026-10-07hn
Show HN: Llama 3.2 3B and Keiro Research achieves 85% on SimpleQAkeirolabs.cloud2026-03-072026-10-07hn
RWKV-7 beats Llama 3.2 with 3x fewer training tokens and formally exceeds TC^0ai.gopubby.com2026-02-232026-10-07hn
Show HN: Recall – open-source local file organizer using Llama 3.2 and Ollamagithub.com2025-12-102026-10-07hn
Load Llama-3.2 WebGPU in the browser from a local foldersimonwillison.net2025-09-092026-10-07hn
Show HN: Fine-tuned Llama 3.2 3B to match 70B models for local transcriptsbilawal.net2025-09-012026-10-07hn
Show HN: MLX.zig – Llama 3.2 in Ziggithub.com2025-03-142026-10-07hn
Run Llama 3.2 3B on your phoneapps.apple.com2025-01-182026-10-07hn
I built this robot and gave it a llama3.2 braintwitter.com2025-01-142026-10-07hn
PydanticAI using Ollama (llama3.2) running locallygithub.com2024-12-062026-10-07hn
Show HN: Llama 3.2 Interpretability with Sparse Autoencodersgithub.com2024-11-212026-10-07hn
Show HN: Finetune Llama 3.2 Vision in a Colabcolab.research.google.com2024-11-212026-10-07hn
LLama3.2-vision as almost perfect OCR?demo.doctractor.com2024-11-182026-10-07hn
Ollama 0.4 is released with support for Meta's Llama 3.2 Vision models locallyollama.com2024-11-062026-10-07hn
I Self-Hosted Llama 3.2 with Coolify on My Home Servergeek.sg2024-10-162026-10-07hn
Implementing the Llama 3.2 1B and 3B Architectures from Scratchgithub.com2024-10-052026-10-07hn
Llama can now see and run on your device – welcome Llama 3.2huggingface.co2024-09-252026-10-07hn
Open Source wireframe to app powered by Llama 3.2 Visionnapkins.dev2024-09-252026-10-07hn
Llama 3.2 1B and 3B on-device modelstwitter.com2024-09-252026-10-07hn
Llama 3.2: Lightweight models for edge devicestwitter.com2024-09-252026-10-07hn
Llama 3.2 Releasegithub.com2024-09-252026-10-07hn
Llama 3.2: Revolutionizing edge AI and vision with open, customizable modelsai.meta.com official2024-09-252026-10-07hn
Download Llama 3.2 1B, 3B, 11B, 90Bllama.com official2024-09-252026-10-07hn
Llama 3.2 released: Multimodal, 1B to 90B sizesllama.com official2024-09-252026-10-07hn

Papers

2 papers

Papers 2

arXiv links found in the model card and its tags. "Peer-reviewed" is shown only with evidence: a published venue in OpenAlex (measured) or the authors' own journal reference on arXiv (reported).

Similar models

3 models

Similar models

  • Qwen2.5-3B-Instruct · 3.09B
    same size band (M), same task (text-generation), fewer providers
  • Qwen2.5-Coder-3B-Instruct · 3.09B
    same size band (M), same task (text-generation), fewer providers
  • Qwen2.5-3B · 3.09B
    same size band (M), same task (text-generation), fewer providers

Sources

5 sources

Sources

Hub snapshot: 2026-10-25 · HF API: 2026-10-24 21:31 UTC · Providers: 2026-10-24 21:44 UTC · Articles: 2026-10-24 21:45 UTC · Summary: 2026-10-07 14:59 UTC · Last verified 2026-10-25

Follow Llama-3.2-3B-Instruct

Watch this model

Email alerts are not open yet; the feeds above are the same data. See feeds for the item schema.