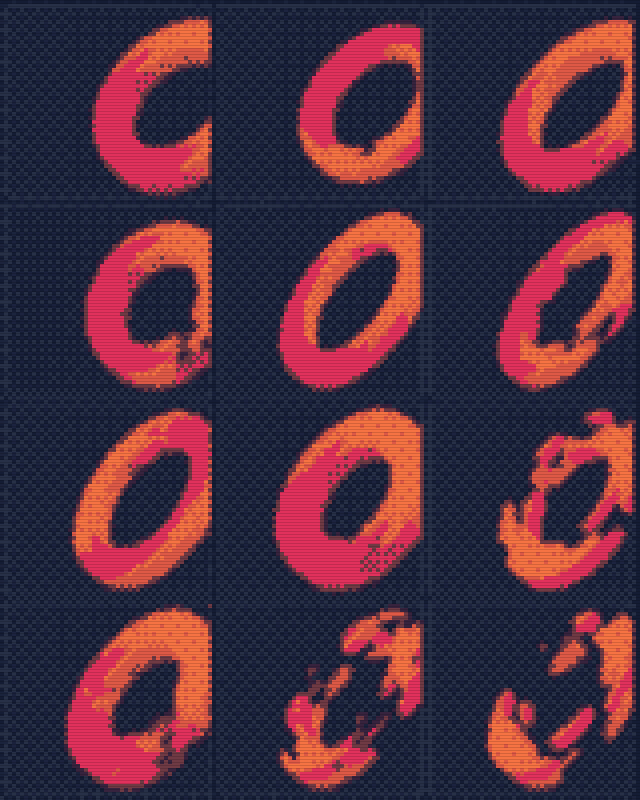Models › Qwen3.5 family

Qwen3.5-397B-A17B

Qwen Apache 2.0 out 8 months ago

403B parameters, 17B active (10 of 512 experts per token), images and text in, text out, 256K tokens of context. 13 providers serve it from $0.68 per million input tokens.

Verified 2026-10-25 Rank #22 in LLMs · score 118.4 method v1 Sources 5 Downloads 30d 733.5k · #135 of 619 tracked

Can I run it?242GB at INT4Estimateneeds a multi-GPU nodemethod
What does it cost?$0.68/1M incheapest of 2Scaleway2026-10-25
Can I use it?Apache 2.0Permissive; patent grantlicence file2026-10-24
Do people use it?733.5kdownloads, 30 days#135 of 619 we track · top 22%+7 likes, downloads +22% this week1,580 likesHugging Face2026-10-24

The ringer: four playful tests

A pelican steals a bicycle from a supermarket

as received● 4/4 on palette
SVG reply: a pelican steals a bicycle from a supermarket
Draw a pelican stealing a bicycle from a supermarket. Reply with one complete SVG document only, no prose and no code fences. Use viewBox="0 0 200 150" and a transparent background. Use only these colours for every fill and stroke: #06e0c0 #ffc298 #cd85f9 #f1f2f2.

Finish the dad joke

as received● 1 line · 10 words

Why did the open-weights model cross the road?

To get to the other side without an API key

Finish this dad joke. Reply with the punchline only, on one line, without quotes: Why did the open-weights model cross the road?

A parasailer, in ASCII

as received● 12×15 fits 12×32
       _
    _-( )-_
  /       \
  \       /
    '-...-'
       |
       |
______|______
|    _____    |
|___|     |___|
~~~~~~~~~~~~~~~
~~~~~~~~~~~~~~~
Draw ASCII art of a parasailer over the sea. At most 12 lines and 32 columns. Reply with the art only: no code fences, no explanation.

Animate a bouncing ball

as received● 8 frames · 16×16
Make a 16x16 pixel sprite animation of a ball bouncing, 8 frames. Reply with JSON only, no code fences: {"palette": {"a": "#rrggbb", ...}, "fps": <number>, "frames": [[16 strings of 16 characters], ...]}. At most 4 palette colours with single-letter keys; "." means transparent; exactly 8 frames.
1 of 4 · swipe for more

The ringer: the same four playful tests for every model, replies shown as received and checked by code. A joke, not a benchmark; never ranked.4 of 4 pass · parasail-qwen35-397b-a17b on parasail · run 2026-10-09 · temperature 0 · cost $0.077 · 2026-10 thing: supermarket · all models →

Worth reading

Picked by rule from 33 tracked pieces: the lab's own post, the most shared, a field report, the latest.

Most discussed · 463 HN pts

Kev: Tiny Jev-like family of decision models built on top of Qwen3.5

Kev is a family of small decision models built on Qwen3.5 and Qwen3.8 that you can train and run locally.

  • The Kev-27B model requires 96–128 GB of RAM on Macs, a requirement marked as expected but not measured.
  • An explicitly requested accelerator fails instead of falling back if the probe times out or crashes.
github.com 2026-09-21 463 HN pts · 210 comments 6.7k words about the Qwen3.5 family family
Latest · 21 days ago

Full-fabric VHDL LLM inference engine. Runs Qwen3.5-class transformer inference

llm.vhdl is a full-fabric VHDL inference engine for Qwen3.5-class models on Xilinx XCVU33P and XCVU35P FPGAs using INT4 streaming matvecs and HBM-resident weights.

  • Reconfiguring the FPGA tears the PCIe bus down and rescans it, which can hang the host if a transaction faults.
  • The inter-die link for the two-die residual hand-off cannot come up because the carrier's refclk oscillator sites are unpopulated.
github.com 2026-10-04 2 HN pts 1.6k words about the Qwen3.5 family family

25 best of 33 tracked

The 2 picks above, plus these 23. Top is the radar's score: discussion, source authority and the lab's own posts, fading with age.

  1. ArticleFixed three bugs that made Qwen3.5-122B a daily driver on Mac Studiomrzk.io · 2026-07-11
  2. CodeWe got 207 tok/s with Qwen3.5-27B on an RTX 3090github.com · 2026-04-20
  3. ArticleQwen3.5: Towards Native Multimodal Agentsqwen.ai · 2026-02-16 · 434 HN pts · official
  4. ArticleQwen3.5 Fine-Tuning Guideunsloth.ai · 2026-03-04 · 416 HN pts
  5. ArticleMacBook M5 Pro and Qwen3.5 = Local AI Security Systemsharpai.org · 2026-03-20 · 173 HN pts
  6. ArticleQwen3.5 122B and 35B models offer Sonnet 4.5 performance on local computersventurebeat.com · 2026-02-28
  7. ArticlePewDiePie uncensors Qwen3.5-9B with Heretictomshardware.com · 2026-10-02
  8. ArticleQwen3.5-Omniqwen.ai · 2026-03-30 · official
  9. DiscussionLaguna S 2.1:118B-a9B better than Qwen3.5:122B-a10B? So far, yesnews.ycombinator.com · 2026-08-06 · 4 HN pts
  10. PaperQwen3.5-Omni Technical Reportarxiv.org · 2026-04-22
  11. ArticleShow HN: Moe Routing Atlas – which experts fire in Qwen3.5/3.6 35B-A3Bgslaller.github.io · 2026-09-29 · 2 HN pts
  12. ArticleQwen3.5-397B-A17B — Architecture, Evals & Inference Performance | InferenceXinferencex.semianalysis.com · undated
  13. Article[AINews] Qwen3.5-397B-A17B: the smallest Open-Opus ...latent.space · undated
  14. DiscussionQwen3.5 50% expert reduction successnews.ycombinator.com · 2026-04-16 · 7 HN pts
  15. ArticleQwen3.5 GGUF Benchmarksunsloth.ai · 2026-02-28
  16. ArticleAsking Qwen3.5-9B, running on 16GB VRAM, to exploit old Windows machinesthepatrickfisher.com · 2026-04-25
  17. CodeQwen3.5-35B – 16GB GPU – 100T/s with 120K context AND vision enabledgithub.com · 2026-03-06
  18. DiscussionShow HN: I ran Qwen3.5 35B on my iPhone at 5.6 tok/SECtwitter.com · 2026-03-21
  19. CodeQwen3.5github.com · 2026-02-16
  20. ArticleQwen3.5-397B-A17B - Everything you need to knowartificialanalysis.ai · 2026-02-17
  21. ArticleQwen3.5: Nobody Agrees on Attention Anymorehuggingface.co · 2026-02-17
  22. ArticleShow HN: llamafile 0.10.0 rebuilt, Qwen3.5, lfm2, Anthropic APIblog.mozilla.ai · 2026-03-19
  23. CodeAdding Support for Qwen3.5github.com · 2026-02-09

Where to run it

Live hosted endpoints, cheapest first, USD per million tokens. Ties break on output price, then provider name.

2 providers from $0.68

2 providers with a live price, from $0.68 to $0.71 per million input tokens; the median is $0.70. One dot per provider, cheapest in teal.

$0.010$0.10$1.00$10.00Scaleway: $0.68 in / $4.10 out per 1M · observed 2026-10-25 · https://huggingface.co/api/models/Qwen/Qwen3.5-397B-A17B?expand[]=inferenceProviderMappingOVHcloud: $0.71 in / $4.25 out per 1M · observed 2026-10-25 · https://huggingface.co/api/models/Qwen/Qwen3.5-397B-A17B?expand[]=inferenceProviderMappingcheapest $0.68median $0.70
$0.010$0.10$1.00$10.00Scaleway: $0.68 in / $4.10 out per 1M · observed 2026-10-25 · https://huggingface.co/api/models/Qwen/Qwen3.5-397B-A17B?expand[]=inferenceProviderMappingOVHcloud: $0.71 in / $4.25 out per 1M · observed 2026-10-25 · https://huggingface.co/api/models/Qwen/Qwen3.5-397B-A17B?expand[]=inferenceProviderMappingcheapest $0.68 · median $0.70 (white tick)
#Cheapest 3In /1MOut /1MContextQuantSeen
1 Scaleway $0.68 $4.10 — — Oct 25
2 OVHcloud $0.71 $4.25 256K — Oct 25
3 Featherless — — — — Oct 25

All 13 providers →

Where it's used

Hugging Face does not say who downloads a model or with what. These are the proxies: API providers listing it, quantized builds, fine-tunes/adapters/merges, and Spaces that load it.

Widely served (13 API providers); heavily run locally (77 quantized builds); a big base for builders (61 fine-tunes, adapters and merges).

  • As a service13Alibaba, AtlasCloud, DeepInfra, DigitalOcean +9
  • On own hardware77quantized builds
  • Built on6140 fine-tunes · 18 adapters · 3 merges
  • In apps100+Hugging Face Spaces

Top Spaces running it: hadadxyz/ai ♥ 819 · pliny-the-prompter/obliteratus ♥ 621 · GenAISecurityProject/OWASP-AIBOM-Generator ♥ 30 · discord-community/HuggingMod ♥ 17

Will it fit?

Weights only, an estimate: leave room for the KV cache. Method

Needs an 8×80 GB node even at INT4

About 242 GB at INT4, 484 GB at FP8, 968 GB at BF16: weights only, so leave room for the KV cache. Every expert must be resident, so total parameters count.

16 GB card64 GB Mac2×80 GB8×80 GBINT4: about 242 GB of weights (estimate; KV cache and activations extra)INT4242 GBFP8: about 484 GB of weights (estimate; KV cache and activations extra)FP8484 GBBF16: about 968 GB of weights (estimate; KV cache and activations extra)BF16968 GB

Estimate params × bytes per param × 1.2 · how we estimate

Day-one receipts

Claim-matched tests, graded by code. Receipts, not a score.

Speed run✕ fail
{
  "providers": [
    {
      "provider": "parasail",
      "endpoint_model": "parasail-qwen35-397b-a17b",
      "source_url": "https://api.parasail.io/v1/chat/completions",
      "ttft_ms_median": null,
      "ttft_any_ms_median": 738,
      "tokens_per_s_median": 81.7,
      "runs": [
        {
          "ttft_s": null,
          "ttft_any_s": 0.752,
          "tokens_per_s": 84.8,
          "latency_s": 17.69,
          "tokens_out": 1500,
          "reasoning_chars": 5474,
          "finish": "length"
        },
        {
          "ttft_s": null,
          "ttft_any_s": 0.738,
          "tokens_per_s": 81.7,
          "latency_s": 18.35,
          "tokens_out": 1500,
          "reasoning_chars": 5470,
          "finish": "length"
        },
        {
          "ttft_s": null,
          "ttft_any_s": 0.654,
          "tokens_per_s": 78.9,
          "latency_s": 19,
          "tokens_out": 1500,
          "reasoning_chars": 5486,
          "finish": "length"
        }
      ]
    }
  ],
  "note": "Single client, wall clock; tok/s counts every output token including hidden reasoning."
}
no visible tokens within 1,500 output tokens (all spent reasoning) · 2026-10-09
Messy addresses to JSON✕ fail
{
  "fields_matched": 0,
  "fields_total": 80,
  "cost_per_1000_usd": 1.0935,
  "parsed": false,
  "per_item": [
    {
      "street": false,
      "city": false,
      "postcode": false,
      "country": false
    },
    {
      "street": false,
      "city": false,
      "postcode": false,
      "country": false
    },
    {
      "street": false,
      "city": false,
      "postcode": false,
      "country": false
    },
    {
      "street": false,
      "city": false,
      "postcode": false,
      "country": false
    },
    {
      "street": false,
      "city": false,
      "postcode": false,
      "country": false
    },
    {
      "street": false,
      "city": false,
      "postcode": false,
      "country": false
    },
    {
      "street": false,
      "city": false,
      "postcode": false,
      "country": false
    },
    {
      "street": false,
      "city": false,
      "postcode": false,
      "country": false
    },
    {
      "street": false,
      "city": false,
      "postcode": false,
      "country": false
    },
    {
      "street": false,
      "city": false,
      "postcode": false,
      "country": false
    },
    {
      "street": false,
      "city": false,
      "postcode": false,
      "country": false
    },
    {
      "street": false,
      "city": false,
      "postcode": false,
      "country": false
    },
    {
      "street": false,
      "city": false,
      "postcode": false,
      "country": false
    },
    {
      "street": false,
      "city": false,
      "postcode": false,
      "country": false
    },
    {
      "street": false,
      "city": false,
      "postcode": false,
      "country": false
    },
    {
      "street": false,
      "city": false,
      "postcode": false,
      "country": false
    },
    {
      "street": false,
      "city": false,
      "postcode": false,
      "country": false
    },
    {
      "street": false,
      "city": false,
      "postcode": false,
      "country": false
    },
    {
      "street": false,
      "city": false,
      "postcode": false,
      "country": false
    },
    {
      "street": false,
      "city": false,
      "postcode": false,
      "country": false
    }
  ],
  "sample": null,
  "fixture": "receipts.addresses.v1"
}
no JSON array in the reply (stopped at the 6,000-token limit while reasoning) · 2026-10-0962.7 s
Needle heatmap● pass
{
  "lengths_k": [
    8,
    32,
    64
  ],
  "depths": [
    0.1,
    0.5,
    0.9
  ],
  "cells": [
    [
      1,
      1,
      1
    ],
    [
      1,
      1,
      1
    ],
    [
      1,
      1,
      1
    ]
  ],
  "detail": [
    {
      "k": 8,
      "depth": 0.1,
      "recalled": true,
      "reply": "amber-falcon-7731",
      "latency_s": 4.69,
      "finish": "stop"
    },
    {
      "k": 8,
      "depth": 0.5,
      "recalled": true,
      "reply": "cobalt-marten-7828",
      "latency_s": 3.35,
      "finish": "stop"
    },
    {
      "k": 8,
      "depth": 0.9,
      "recalled": true,
      "reply": "saffron-newt-7925",
      "latency_s": 4.41,
      "finish": "stop"
    },
    {
      "k": 32,
      "depth": 0.1,
      "recalled": true,
      "reply": "jade-lynx-8022",
      "latency_s": 6.15,
      "finish": "stop"
    },
    {
      "k": 32,
      "depth": 0.5,
      "recalled": true,
      "reply": "umber-kestrel-8119",
      "latency_s": 5.94,
      "finish": "stop"
    },
    {
      "k": 32,
      "depth": 0.9,
      "recalled": true,
      "reply": "coral-heron-8216",
      "latency_s": 5.18,
      "finish": "stop"
    },
    {
      "k": 64,
      "depth": 0.1,
      "recalled": true,
      "reply": "slate-badger-8313",
      "latency_s": 6.55,
      "finish": "stop"
    },
    {
      "k": 64,
      "depth": 0.5,
      "recalled": true,
      "reply": "ochre-otter-8410",
      "latency_s": 6.16,
      "finish": "stop"
    },
    {
      "k": 64,
      "depth": 0.9,
      "recalled": true,
      "reply": "teal-ibis-8507",
      "latency_s": 6.09,
      "finish": "stop"
    }
  ]
}

The story so far

Weights, every dated article, and repo commits on one rail.

8 dated articles and 28 repo commits so far

Teal is the weights (2026-02-16), amber triangles are 8 dated articles (each links to it), grey ticks are repo commits.

What people built on it

138 derivatives on the Hub. Which build to run, by runtime: the most downloaded in each class.

138 derivatives on the Hub, most of them quantized

From the Hugging Face model tree; quantized builds in teal, fine-tunes, merges and adapters in greys.

77 quantized (Hugging Face model tree)40 fine-tunes (Hugging Face model tree)3 merges (Hugging Face model tree)18 adapters (Hugging Face model tree)77 quantized40 fine-tunes3 merges18 adapters

All variants →

Reference

Everything else, folded: the full tables, every source.

Benchmarks

8 rows

Benchmarks 8 rows

measured third-party leaderboard rowauthor-reported number from the model card or eval files (8)No confidence intervals unless the source gave them; settings differ between rows, so compare within a benchmark, not across. Date = the benchmark's own date when it gives one, else when we read it.
BenchmarkValueSetting / notesReported byDate
author-reported AA-LCR · Read long documents68.7—model author2026-10-07
author-reported C-Eval · Work across languages93—model author2026-10-07
author-reported IFBench · Chat and follow instructions76.5—model author2026-10-07
author-reported IFEval · Chat and follow instructions92.6—model author2026-10-07
author-reported MMLU · Reason through hard problems94.9—model author2026-10-07
author-reported MMLU-Pro · Reason through hard problems87.8—model author2026-10-07
author-reported MultiChallenge · Chat and follow instructions67.6—model author2026-10-07
author-reported SuperGPQA · Reason through hard problems70.4—model author2026-10-07

Use-case evidence

7 use cases

Facts

23 fields

Listed in LLMs · MoE

Facts

Pipeline tagimage-text-to-text
Librarytransformers
ArchitecturesQwen3_5MoeForConditionalGeneration
Model typeqwen3_5_moe
Dtypebfloat16
Params by dtypeBF16: 403,397,920,304 · F32: 8,640
Size bandXXL
MoEyes
Experts512
Experts per token10
Context length262,144 (config.json max_position_embeddings)
LicenseApache 2.0 (apache-2.0)
Hub snapshot2026-10-25

Servability

vLLM · SGLang

Servability

vLLM: supported · Qwen3_5MoeForConditionalGeneration · 7050ef881ff0835f6890a47db1859a24c65481d6SGLang: supported · Qwen3_5MoeForConditionalGeneration · 773cb938fe9484a8f7e7e46fb1b1fe96412c59ed

vLLM registry (7050ef881ff0835f6890a47db1859a24c65481d6) · SGLang registry (773cb938fe9484a8f7e7e46fb1b1fe96412c59ed) · Matched by architecture class name against each project's registry on main; 'supported' means the architecture is registered, not that this checkpoint was tested.

Hardware fit

3 estimates

Hardware fit ESTIMATE

Weights-only memory for Qwen3.5-397B-A17B: params × bytes/param × 1.2 overhead. KV cache and activations are extra. How this is computed.

BF16 (2 bytes/param)968 GB · Cluster (≥640 GB)
FP8 (1 byte/param)484 GB · Multi-GPU node (<640 GB)
INT4 (0.5 bytes/param)242 GB · Multi-GPU node (<640 GB)

Weights only (params × bytes/param × 1.2 overhead); KV cache and activations extra. MoE: all experts must be resident, so total parameters count.

All variants

40 variants

Lineage

Original model Family: Qwen/Qwen3.5 138 derivatives on the Hub

quantized: 77finetune: 40adapter: 18merge: 3

Top variants (40 shown, ranked by downloads)

Relation
Quant
Size
40 rows
Variant Relation Quant Params Band License Author Likes Downloads
Qwen/Qwen3.5-397B-A17B-FP8 quantized -FP8 403B XXL apache-2.0 Qwen 193 6.7M
nvidia/Qwen3.5-397B-A17B-NVFP4 quantized NVFP4 204B XXL apache-2.0 nvidia 113 3.1M
unsloth/Qwen3.5-397B-A17B-GGUF quantized GGUF — — apache-2.0 unsloth 254 1.1M
tiny-random/qwen3.5-moe finetune — 4.90M S — tiny-random 4 392.1k
timteh673/Qwen3.5-397B-A17B-Opus-4.6-Reasoning-Uncensored-GGUF adapter GGUF — — apache-2.0 timteh673 29 374.7k
cyankiwi/Qwen3.5-397B-A17B-AWQ-4bit quantized AWQ 70.2B XL apache-2.0 cyankiwi 3 375.2k
bartowski/Qwen_Qwen3.5-397B-A17B-GGUF quantized GGUF — — apache-2.0 bartowski 12 275.4k
Intel/Qwen3.5-397B-A17B-int4-AutoRound quantized int4 — — — Intel 19 259.2k
lmstudio-community/Qwen3.5-397B-A17B-MLX-8bit quantized MLX 397B XXL apache-2.0 lmstudio-community 2 213k
prefeitura-rio/Rio-3.5-Open-397B finetune — — — mit prefeitura-rio 329 191.5k
Qwen/Qwen3.5-397B-A17B-GPTQ-Int4 quantized GPTQ 403B XXL apache-2.0 Qwen 43 187.2k
nvidia/Qwen3.5-397B-A17B-NVFP4-V2 quantized NVFP4 — — apache-2.0 nvidia 18 152.8k
mlx-community/Qwen3.5-397B-A17B-8bit quantized -8bit 397B XXL apache-2.0 mlx-community 5 119.1k
QuantTrio/Qwen3.5-397B-A17B-AWQ quantized AWQ — — apache-2.0 QuantTrio 9 73.1k
lukealonso/Qwen3.5-397B-A17B-NVFP4 quantized NVFP4 — — apache-2.0 lukealonso 10 53.9k
lmstudio-community/Qwen3.5-397B-A17B-MLX-4bit quantized MLX 397B XXL apache-2.0 lmstudio-community 0 53.1k
unsloth/Qwen3.5-397B-A17B-MTP-GGUF quantized GGUF — — apache-2.0 unsloth 19 37k
lmstudio-community/Qwen3.5-397B-A17B-MLX-6bit quantized MLX 397B XXL apache-2.0 lmstudio-community 1 30.7k
nohurry/Qwen3.5-397B-A17B-TQ1_0-GGUF quantized GGUF — — apache-2.0 nohurry 4 25.3k
ubergarm/Qwen3.5-397B-A17B-GGUF quantized GGUF — — apache-2.0 ubergarm 38 23.2k
Goldkoron/Qwen3.5-397B-A17B quantized GGUF — — apache-2.0 Goldkoron 7 24.5k
AesSedai/Qwen3.5-397B-A17B-GGUF quantized GGUF — — — AesSedai 30 22.4k
rene98c/Qwen3.5-397B-A17B-REAP-28-NVFP4 quantized NVFP4 — — apache-2.0 rene98c 5 23.4k
amd/Qwen3.5-397B-A17B-MXFP4-AttnFP8-V2 quantized MXFP4 203B XXL apache-2.0 amd 0 23.5k
vincentzed-hf/Qwen3.5-397B-A17B-NVFP4 quantized NVFP4 — — apache-2.0 vincentzed-hf 11 21.9k
XYZAILab/XYZ-Aquila-pro finetune — 397B XXL apache-2.0 XYZAILab 380 3.1k
z-lab/Qwen3.5-397B-A17B-DFlash finetune — 1.29B S apache-2.0 z-lab 10 17.1k
RedHatAI/Qwen3.5-397B-A17B-FP8-dynamic quantized -FP8 404B XXL apache-2.0 RedHatAI 6 16.6k
Goldkoron/Qwen3.5-397B-A17B-REAP35 quantized GGUF — — apache-2.0 Goldkoron 7 15.6k
mudler/Qwen3.5-397B-A17B-APEX-GGUF quantized GGUF — — apache-2.0 mudler 3 13.7k
Sehyo/Qwen3.5-397B-A17B-NVFP4 quantized NVFP4 — — — Sehyo 7 11.9k
lmstudio-community/Qwen3.5-397B-A17B-GGUF quantized GGUF — — apache-2.0 lmstudio-community 0 11.6k
mlx-community/Qwen3.5-397B-A17B-nvfp4 quantized nvfp4 396B XXL apache-2.0 mlx-community 5 10.3k
mradermacher/Qwen3.5-397B-A17B-i1-GGUF quantized GGUF — — apache-2.0 mradermacher 2 6.7k
DevQuasar/Qwen.Qwen3.5-397B-A17B-GGUF quantized GGUF — — — DevQuasar 2 6.4k
SilverMan99/Qwen3.5-397B-A17B-Opus-4.6-Reasoning-Uncensored-GGUF adapter GGUF — — apache-2.0 SilverMan99 2 5.1k
yujiepan/qwen3.5-moe-tiny-random finetune — 4.90M S — yujiepan 3 4.7k
amd/Qwen3.5-397B-A17B-NVFP4 quantized NVFP4 204B XXL apache-2.0 amd 1 4.6k
TheDrainFlorist/Qwen3.5-397B-A17B-VQ-2.4bpw quantized 4bpw 120B XXL apache-2.0 TheDrainFlorist 0 4.4k
TheDrainFlorist/Qwen3.5-397B-A17B-VQ-2.2bpw quantized 2bpw 62.6B XL apache-2.0 TheDrainFlorist 0 4.3k

Repository changelog

28 commits

Repository changelog 28 commits

DateCommitSHA
2026-04-24 Update README.md 8472618
2026-04-24 fix: rename response variable to chat_response in README code example 848662a
2026-03-15 Update medical vqa score (#65) 60c2d3e
2026-02-23 Update README.md 98d1a50
2026-02-20 add KTransformers deployment guide (#30) 285b7b5
2026-02-16 Update README.md 7cad2ba
2026-02-16 Fix README accessibility: enable adaptive light/dark theme for tables (#8) 076f1b8
2026-02-16 Update README.md 59a9aaa
2026-02-16 Update README.md eb9e569
2026-02-16 Update README.md e4528a6
2026-02-16 Update README.md 0674dbe
2026-02-16 Upload generation_config.json 167684e
2026-02-16 Update README.md f34a529
2026-02-16 Update tokenizer_config.json 646a873
2026-02-16 Update README.md 60a0388
2026-02-16 Update README.md ac720d0
2026-02-16 Update README.md 786331b
2026-02-16 Upload LICENSE 7f74e13
2026-02-16 Update video_preprocessor_config.json 5ff2660
2026-02-16 Update tokenizer_config.json 5523f9e
2026-02-16 Update chat_template.jinja 65e34c6
2026-02-16 Update README.md fe5a6d3
2026-02-16 Update README.md 0b7c9bf
2026-02-16 Create README.md (#1) 47a4bd1
2026-02-16 Add files using upload-large-folder tool 2e0ff47
2026-02-16 Add files using upload-large-folder tool 7090120
2026-02-16 Add files using upload-large-folder tool 556af78
2026-02-16 initial commit 5f47827

All providers

13 providers · 13 endpoints

Where to run 13 providers · 13 endpoints

Hosted endpoints observed for Qwen3.5-397B-A17B, sorted by input price (USD per million tokens). Each row names its observer and date; prices change daily, so check the source before quoting. Cheapest observed input price: $0.39/M.

ProviderModel refContextQuant$/M in$/M outtok/sTTFTToolsStatusObserved
Alibaba
openrouter
qwen/qwen3.5-397b-a17b 256K unknown $0.39 $2.34 — — yes status -5 2026-10-24
DeepInfra
hf, deepinfra, openrouter
Qwen/Qwen3.5-397B-A17B 256K fp8 $0.45 $3.00 62.7 626 ms yes status -2 2026-10-25
Parasail
parasail, openrouter
parasail-qwen35-397b-a17b 256K fp8 $0.50 $3.60 — — yes status -2 2026-10-24
DigitalOcean
openrouter
qwen/qwen3.5-397b-a17b 128K unknown $0.55 $3.50 — — yes status -2 2026-10-24
Phala
openrouter
qwen/qwen3.5-397b-a17b 256K unknown $0.55 $3.50 — — yes status -5 2026-10-24
AtlasCloud
openrouter
qwen/qwen3.5-397b-a17b 256K fp8 $0.55 $3.50 — — yes status -5 2026-10-24
Novita
hf, openrouter
qwen/qwen3.5-397b-a17b 256K unknown $0.60 $3.60 60.1 1528 ms yes status -5 2026-10-25
StreamLake
openrouter
qwen/qwen3.5-397b-a17b 250K unknown $0.60 $3.60 — — — status -2 2026-10-24
GMICloud
openrouter
qwen/qwen3.5-397b-a17b 256K fp8 $0.60 $3.60 — — yes status -5 2026-10-24
Scaleway
hf
qwen3.5-397b-a17b — — $0.68 $4.10 92.8 396 ms yes live 2026-10-25
OVHcloud
hf
Qwen3.5-397B-A17B 256K — $0.71 $4.25 96.7 467 ms yes live 2026-10-25
Venice
openrouter
qwen/qwen3.5-397b-a17b 125K unknown $0.75 $4.50 — — yes status -5 2026-10-24
Featherless
hf
Qwen/Qwen3.5-397B-A17B — — — — — — — live 2026-10-25

Articles and coverage

33 pieces

Ranked by source signals (HN, Lobsters, authority domains, official posts) and recency. Summaries are generated from a stored copy of the article text; every sentence cites a span of that text, and nothing is shown that failed the citation check.

Official2

qwen.ai2026-02-16officialauthorityHN front pageabout the Qwen3.5 familyHN 434 pts · 214 comments17,678 words
Qwen3.5-397B-A17B is the first open-weight native vision-language model in the Qwen3.5 series, released on 2026/02/15. Built on a hybrid architecture fusing linear attention via Gated Delta Networks with a sparse mixture-of-experts, it activates just 17 billion parameters per forward pass despite comprising 397 billion total parameters. The model expanded language support from 119 to 201 languages while matching the >1T-parameter Qwen3-Max-Base capability.written, reviewed, cited
  • The hosted Qwen3.5-Plus model defaults to a 1M context window and includes official built-in tools with adaptive tool use.
  • For the BrowseComp benchmark, the model achieved a score of 69.0 using simple context-folding, while the discard-all strategy reached 78.6.
unsloth.ai2026-03-04authorityHN front pageabout the Qwen3.5 familyHN 416 pts · 107 comments729 words
Engineers can fine-tune the Qwen3.5 model family (0.8B, 2B, 4B, 9B, 27B, 35B-A3B, 122B-A10B) with Unsloth, which trains models 1.5 times faster using 50% less VRAM than FA2 setups. VRAM requirements for bf16 LoRA range from 3GB for the 0.8B model to 56GB for the 27B model, while the 35B-A3B variant operates on 74GB VRAM and the 122B-A10B on 256GB VRAM. MoE fine-tuning leverages a recent update delivering over 35% less VRAM usage and approximately 6x longer context support.written, reviewed, cited
  • To preserve reasoning ability, mix reasoning-style examples with direct answers while keeping a minimum of 75% reasoning.
  • Router-layer fine-tuning is disabled by default for stability on MoE models like Qwen3.5‑35B‑A3B.
  • You can run Qwen3.5 RL with Unsloth even though it is not supported by vLLM by setting fast_inference=False.

Analysis6

github.com2026-09-21authorityHN front pageabout the Qwen3.5 familyHN 463 pts · 210 comments6,746 words
Kev is a family of small decision models built on Qwen3.5 and Qwen3.8 that you can train and run locally. The API matches TypeSafe's System One, so you can point their Python SDK at your local server. Models use a small adapter on a frozen base, except Kev-27B which ships as 51 GB of full weights. The 27B model achieves 0.851 accuracy on new sources.written, reviewed, cited
  • The Kev-27B model requires 96–128 GB of RAM on Macs, a requirement marked as expected but not measured.
  • An explicitly requested accelerator fails instead of falling back if the probe times out or crashes.
github.com2026-10-04authorityabout the Qwen3.5 familyHN 2 pts · 0 comments1,558 words
llm.vhdl is a full-fabric VHDL inference engine for Qwen3.5-class models on Xilinx XCVU33P and XCVU35P FPGAs using INT4 streaming matvecs and HBM-resident weights. It supports single-card 9B or two-card 27B configurations, achieving about 2.5 tokens/s on silicon at 75 MHz. The 27B target fits a VU35P at about 46% LUT but requires the Jungle Cat board, which lacks PCIe and relies on slow Ethernet or JTAG for weight loading.written, reviewed, cited
  • Reconfiguring the FPGA tears the PCIe bus down and rescans it, which can hang the host if a transaction faults.
  • The inter-die link for the two-die residual hand-off cannot come up because the carrier's refclk oscillator sites are unpopulated.
  • The Jungle Cat board lacks PCIe, forcing weight loading over a CoE/JTAG bridge that operates at roughly 1 MB/s.
sharpai.org2026-03-20HN front pageabout the Qwen3.5 familyHN 173 pts · 152 comments1,458 words
gslaller.github.io2026-09-29about the Qwen3.5 familyHN 2 pts · 0 comments
inferencex.semianalysis.comauthority
latent.spaceauthority

Community2

news.ycombinator.com2026-08-06about the Qwen3.5 familyHN 4 pts · 2 comments157 words
This American (San Francisco) model, Laguna S 2.1:118B-a9B, outperforms Qwen3.5:122B-a10B and Sonnet in current benchmarking tests. It demonstrates better personality and natural creativity when designing UIs. Benchmarks need to include a minimum of hardware requirements, which are currently missing.written, reviewed, cited
news.ycombinator.com2026-04-16about the Qwen3.5 familyHN 7 pts · 2 comments
All coverage tracked for this model (33) — append-only, nothing is ever removed
TitleSourcePublishedFirst seenSignals
Qwen3.5-397B-A17B — Architecture, Evals & Inference Performance | InferenceXinferencex.semianalysis.com—2026-10-07exa
[AINews] Qwen3.5-397B-A17B: the smallest Open-Opus ...latent.space—2026-10-07exa
Qwen 3.5: All 8 Models, Benchmarks & Local Setup Guideqwen-ai.com—2026-10-07exa
Qwen3.5-397B-A17B by Alibaba / Qwen: Complete Performance Review & Benchmarks (2026)airank.dev—2026-10-07exa
Full-fabric VHDL LLM inference engine. Runs Qwen3.5-class transformer inferencegithub.com2026-10-042026-10-07hn
PewDiePie uncensors Qwen3.5-9B with Heretictomshardware.com2026-10-022026-10-07hn
Show HN: Moe Routing Atlas – which experts fire in Qwen3.5/3.6 35B-A3Bgslaller.github.io2026-09-292026-10-07hn
Kev: Tiny Jev-like family of decision models built on top of Qwen3.5github.com2026-09-212026-10-07hn
Laguna S 2.1:118B-a9B better than Qwen3.5:122B-a10B? So far, yesnews.ycombinator.com2026-08-062026-10-07hn
Fixed three bugs that made Qwen3.5-122B a daily driver on Mac Studiomrzk.io2026-07-112026-10-07hn
Asking Qwen3.5-9B, running on 16GB VRAM, to exploit old Windows machinesthepatrickfisher.com2026-04-252026-10-07hn
Qwen3.5-Omni Technical Reportarxiv.org2026-04-222026-10-07hn
We got 207 tok/s with Qwen3.5-27B on an RTX 3090github.com2026-04-202026-10-07hn
Qwen3.5 50% expert reduction successnews.ycombinator.com2026-04-162026-10-07hn
Are Local LLMs Good Enough for Vibe Coding? Gemma4-26B-A4B vs. Qwen3.5-35B-A3Bgrigio.org2026-04-072026-10-07hn
Unlocking LoRA Moe RL for Qwen3.5osmosis.ai2026-04-032026-10-07hn
Qwen3.5-Omniqwen.ai official2026-03-302026-10-07hn
Show HN: I ran Qwen3.5 35B on my iPhone at 5.6 tok/SECtwitter.com2026-03-212026-10-07hn
MacBook M5 Pro and Qwen3.5 = Local AI Security Systemsharpai.org2026-03-202026-10-07hn
Show HN: llamafile 0.10.0 rebuilt, Qwen3.5, lfm2, Anthropic APIblog.mozilla.ai2026-03-192026-10-07hn
AI on a Budget: Recompiling Llama.cpp for Qwen3.5 Inference on an HP Z440jeanbaptistefleury.neocities.org2026-03-102026-10-07hn
Qwen3.5-35B – 16GB GPU – 100T/s with 120K context AND vision enabledgithub.com2026-03-062026-10-07hn
Qwen3.5 Fine-Tuning Guideunsloth.ai2026-03-042026-10-07hn
Qwen3.5 122B and 35B models offer Sonnet 4.5 performance on local computersventurebeat.com2026-02-282026-10-07hn
Qwen3.5 GGUF Benchmarksunsloth.ai2026-02-282026-10-07hn
Mediummedium.com2026-02-182026-10-07exa
Qwen3.5-397B-A17B - Everything you need to knowartificialanalysis.ai2026-02-172026-10-07exa
Qwen3.5: Nobody Agrees on Attention Anymorehuggingface.co2026-02-172026-10-07exa
Qwen3.5github.com2026-02-162026-10-07hn
Qwen3.5: Towards Native Multimodal Agentsqwen.ai official2026-02-162026-10-07hn
Qwen3.5-397B-A17B — benchmarks, pricing & hardware fit · Model Beatsmodelbeats.com2026-02-162026-10-07exa
Qwen 3.5: 397B MoE Benchmarks, Pricing & Complete Guidedigitalapplied.com2026-02-152026-10-07exa
Adding Support for Qwen3.5github.com2026-02-092026-10-07hn

Similar models

3 models

Similar models

  • MiniMax-M3 · 427B
    same size band (XXL), also MoE, same task (image-text-to-text)
  • GLM-5.3-Flash · 321B
    same size band (XXL), also MoE, same task (image-text-to-text), more providers, permissive license
  • DeepSeek-V4-Flash-Vision-Exp · 305B
    same size band (XXL), also MoE, same task (image-text-to-text), fewer providers, permissive license

Sources

5 sources

Sources

Hub snapshot: 2026-10-25 · HF API: 2026-10-24 21:31 UTC · Providers: 2026-10-24 21:44 UTC · Articles: 2026-10-24 21:45 UTC · Summary: 2026-10-07 14:59 UTC · Last verified 2026-10-25

Follow Qwen3.5-397B-A17B

Watch this model

Email alerts are not open yet; the feeds above are the same data. See feeds for the item schema.