
The lab's own post
filecdn.minimax.chat 2026-06-01 3 HN pts · 1 comments sells inference
Up to date
MiniMaxAI MiniMax Model License (minimax-community) out 5 months ago
427B parameters (4 of 128 experts per token), images and text in, text out, 1M tokens of context. 14 providers serve it from $0.22 per million input tokens.
Verified 2026-10-25 Rank #24 in LLMs · score 117.9 method v1 Sources 5 Downloads 30d 203.5k · #251 of 619 tracked
Changed this week: 1 new quantized build on the Hub (58 in all).2026-10-24
Picked by rule from 22 tracked pieces: the lab's own post, the most shared, a field report, the latest.
MiniMax M3 used a fixed one-second background tick while GLM 5.2 employed a heap for more idle-efficient scheduling.
Thinkbench evaluated GLM 5.2 and MiniMax M3 on autonomous coding tasks involving greenfield builds and bug fixes.
Fireworks released a KV-stationary kernel for MiniMax M3 sparse attention on NVIDIA Blackwell that loads each selected KV block once to reduce memory traffic.
The 5 picks above, plus these 17. Top is the radar's score: discussion, source authority and the lab's own posts, fading with age.
Live hosted endpoints, cheapest first, USD per million tokens. Ties break on output price, then provider name.
11 providers with a live price, from $0.22 to $0.30 per million input tokens; the median is $0.30. One dot per provider, cheapest in teal.
Hugging Face does not say who downloads a model or with what. These are the proxies: API providers listing it, quantized builds, fine-tunes/adapters/merges, and Spaces that load it.
Widely served (14 API providers); heavily run locally (58 quantized builds).
Top Spaces running it: smolagents/ml-intern ♥ 423 · MiniMaxAI/MiniMax-Music3-workflow ♥ 28 · akhaliq/MiniMax-Music3-workflow ♥ 8 · finerobotics/annotation-studio ♥ 4
Weights only, an estimate: leave room for the KV cache. Method
About 256 GB at INT4, 512 GB at FP8, 1.02 TB at BF16: weights only, so leave room for the KV cache. Every expert must be resident, so total parameters count.
Estimate params × bytes per param × 1.2 · how we estimate
Claim-matched tests, graded by code. Receipts, not a score.
{
  "providers": [
    {
      "provider": "parasail",
      "endpoint_model": "parasail-minimax-m3",
      "source_url": "https://api.parasail.io/v1/chat/completions",
      "ttft_ms_median": 1259,
      "ttft_any_ms_median": 632,
      "tokens_per_s_median": 118.4,
      "runs": [
        {
          "ttft_s": 1.347,
          "ttft_any_s": 0.632,
          "tokens_per_s": 118.4,
          "latency_s": 2.52,
          "tokens_out": 298,
          "reasoning_chars": 463,
          "finish": "stop"
        },
        {
          "ttft_s": 1.259,
          "ttft_any_s": 0.737,
          "tokens_per_s": 109.8,
          "latency_s": 2.58,
          "tokens_out": 283,
          "reasoning_chars": 474,
          "finish": "stop"
        },
        {
          "ttft_s": 1.134,
          "ttft_any_s": 0.585,
          "tokens_per_s": 145.7,
          "latency_s": 2.02,
          "tokens_out": 294,
          "reasoning_chars": 488,
          "finish": "stop"
        }
      ]
    }
  ],
  "note": "Single client, wall clock; tok/s counts every output token including hidden reasoning."
} {
"calls": [],
"checks": {
"get_weather": false,
"check_calendar": false,
"book_table": false
},
"final": "I'll check the weather and your calendar in parallel first.]<]minimax[>[<tool_call>\n]<]minimax[>[<invoke name=\"get_weather\">]<]minimax[>[ city>Lisbon]<]minimax[>[</city>]<]minimax[>[<date>2026-10-14]<]minimax[>[</date>]<]minimax[>[</invoke>\n]<]minimax[>[<invoke name=\"check_calendar\">]<]minimax[>[<date>2026-10-14]<]minimax[>[</date>]<]minimax[>[</invoke>\n]<]minimax[>[</tool_call>",
"fixture": "receipts.errand.v1"
} Weights, every dated article, and repo commits on one rail.
Teal is the weights (2026-06-02), amber triangles are 8 dated articles (each links to it), grey ticks are repo commits.
73 derivatives on the Hub. Which build to run, by runtime: the most downloaded in each class.
From the Hugging Face model tree; quantized builds in teal, fine-tunes, merges and adapters in greys.
Everything else, folded: the full tables, every source.
| Benchmark | Value | Setting / notes | Reported by | Date |
|---|---|---|---|---|
| author-reported lhtb (IntelligenceLab/Long-Horizon-Terminal-Bench) | 38.5 | mean reward x100 over 46 tasks (partial credit); [email protected]=3/46; official LHTB Harbor harness | LHTB leaderboard | 2026-07-16 |
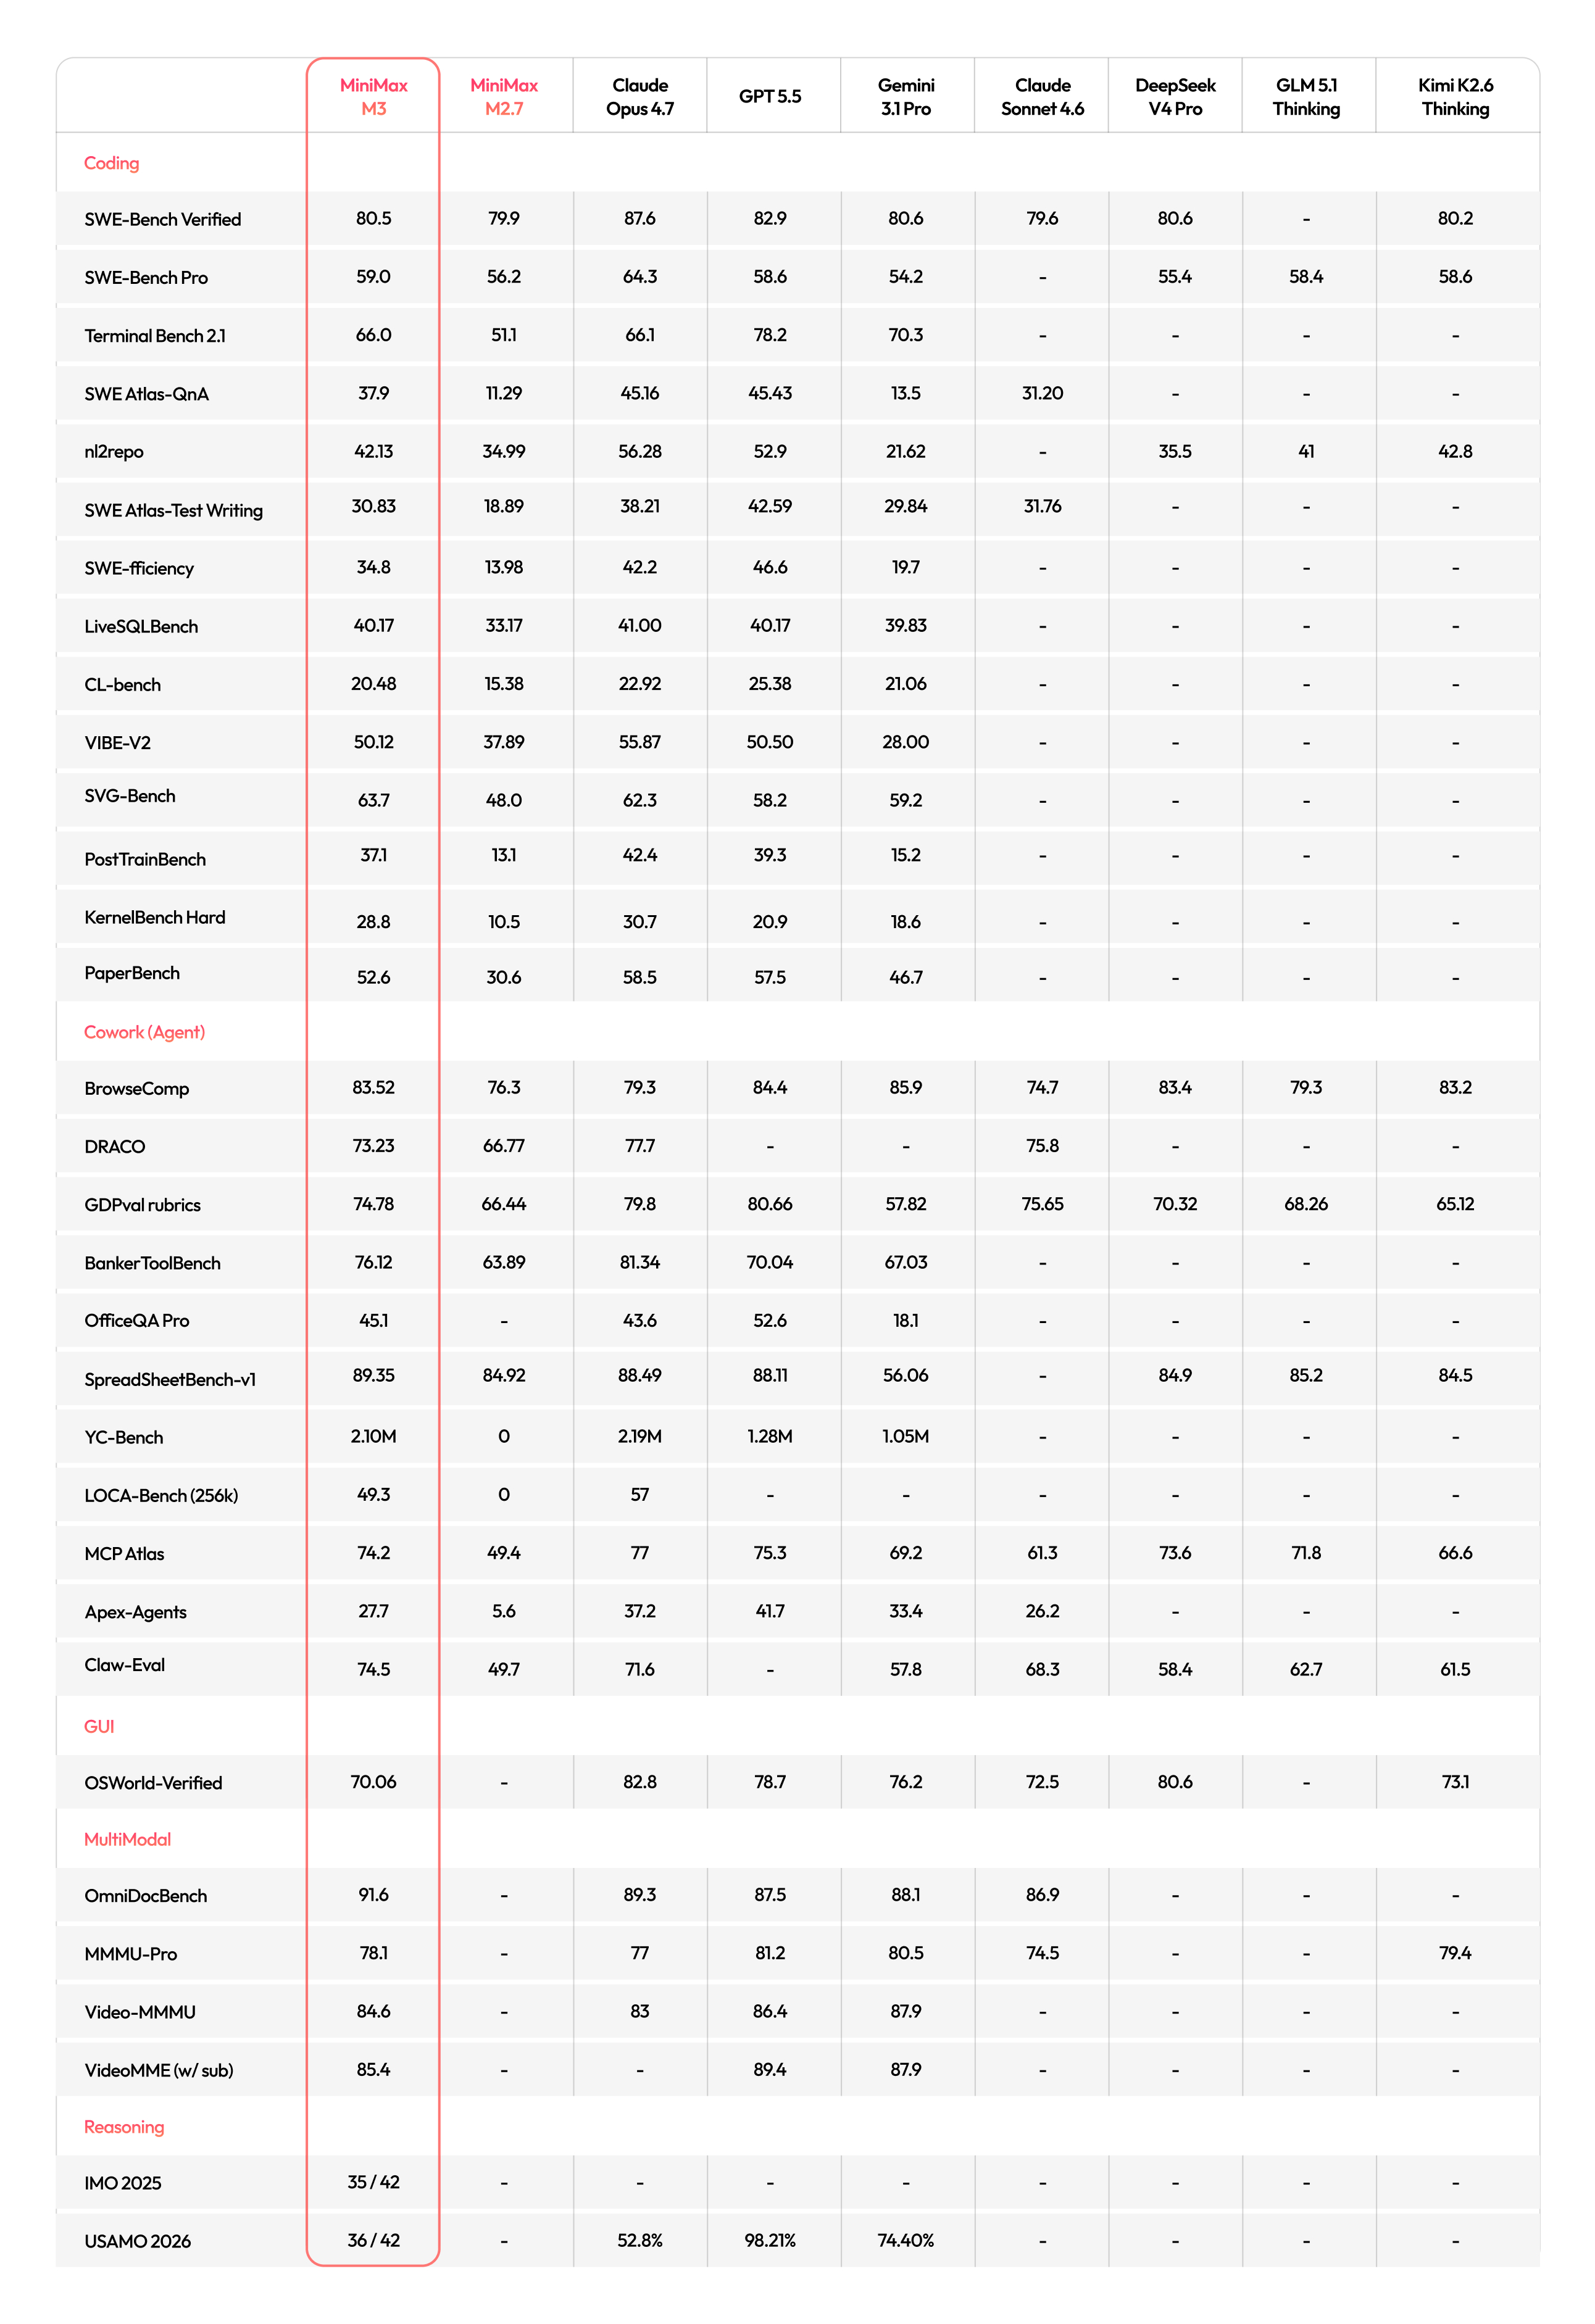
| author-reported swe_bench_%_resolved (SWE-bench/SWE-bench_Verified) | 80.5 | Evaluated on internal infrastructure using Claude Code as the scaffolding. Each test was run 4 times and the average was taken. | MiniMax-M3 model card | 2026-10-24 |
| author-reported SWE_Bench_Pro (ScaleAI/SWE-bench_Pro) | 59 | Evaluated on internal infrastructure using Claude Code as the scaffolding. Testing logic is aligned with the official evaluation. | MiniMax-M3 model card | 2026-10-24 |
| author-reported mmmu_pro_standard_10_options (MMMU/MMMU_Pro) | 78.1 | MMMU-Pro score extracted from the model card benchmark graph. The exact task variant (vision, standard 4-options, or standard 10-options) is not explicitly stated. | MiniMax-M3 model card | 2026-10-24 |
| author-reported video-mme-v2 (MME-Benchmarks/Video-MME-v2) | 85.4 | Model card reports 'VideoMME (w/ sub)'. Mapped to the closest registered benchmark on the Hub, Video-MME-v2. | MiniMax-M3 model card | 2026-10-24 |
| author-reported general (claw-eval/Claw-Eval) | 74.5 | Model card reports a single 'Claw-Eval' score. Mapped to the 'general' task (overall); the exact task split is not specified. | MiniMax-M3 model card | 2026-10-24 |
| author-reported apex-agents (mercor/apex-agents) | 27.7 | Evaluated on the apex-agents benchmark. | MiniMax-M3 model card | 2026-10-24 |
| author-reported medium (collinear-ai/yc-bench) | 2100000 | Model card reports 2.1M (monetary value, final assets fund). The benchmark's 'medium' task is used as the overall evaluation. Metric is monetary, not percentage-based. | MiniMax-M3 model card | 2026-10-24 |
Labels are evidence, not verdicts: measured a third-party leaderboard row for this model; author-reported a number the model author published in the card or eval files; structural a deterministic signal from the name, config or chat template, or a decision-model estimate. Each chip links to its source. All use cases.
| Pipeline tag | image-text-to-text |
|---|---|
| Library | transformers |
| Architectures | MiniMaxM3SparseForConditionalGeneration |
| Model type | minimax_m3_vl |
| Dtype | bfloat16 |
| Params by dtype | BF16: 426,993,800,960 · F32: 46,339,200 |
| Size band | XXL |
| MoE | yes |
| Experts | 128 |
| Experts per token | 4 |
| Context length | 1,048,576 (config.json max_position_embeddings) |
| Papers | arXiv:2606.13392 |
| License | MiniMax Model License (minimax-community) (other) |
| Hub snapshot | 2026-10-25 |
vLLM: supported · MiniMaxM3SparseForConditionalGeneration · 7050ef881ff0835f6890a47db1859a24c65481d6SGLang: supported · MiniMaxM3SparseForConditionalGeneration · 773cb938fe9484a8f7e7e46fb1b1fe96412c59ed
vLLM registry (7050ef881ff0835f6890a47db1859a24c65481d6) · SGLang registry (773cb938fe9484a8f7e7e46fb1b1fe96412c59ed) · Matched by architecture class name against each project's registry on main; 'supported' means the architecture is registered, not that this checkpoint was tested.
Weights-only memory for MiniMax-M3: params × bytes/param × 1.2 overhead. KV cache and activations are extra. How this is computed.
| BF16 (2 bytes/param) | 1.02 TB · Cluster (≥640 GB) |
|---|---|
| FP8 (1 byte/param) | 512 GB · Multi-GPU node (<640 GB) |
| INT4 (0.5 bytes/param) | 256 GB · Multi-GPU node (<640 GB) |
Weights only (params × bytes/param × 1.2 overhead); KV cache and activations extra. MoE: all experts must be resident, so total parameters count.
quantized: 58finetune: 14adapter: 1
| Variant | Relation | Quant | Params | Band | License | Author | Likes | Downloads |
|---|---|---|---|---|---|---|---|---|
| MiniMaxAI/MiniMax-M3-MXFP8 | quantized | — | 427B | XXL | other | MiniMaxAI | 61 | 1.8M |
| nvidia/MiniMax-M3-NVFP4 | quantized | NVFP4 | 220B | XXL | other | nvidia | 91 | 944.2k |
| amd/MiniMax-M3-MXFP4 | quantized | MXFP4 | 232B | XXL | other | amd | 5 | 631.7k |
| unsloth/MiniMax-M3-GGUF | quantized | GGUF | — | — | other | unsloth | 170 | 72.9k |
| cyankiwi/MiniMax-M3-AWQ-INT4 | quantized | AWQ | 427B | XXL | other | cyankiwi | 10 | 64.2k |
| EmbeddedLLM/MiniMax-M3-FP8-dynamic | quantized | -FP8 | 427B | XXL | other | EmbeddedLLM | 2 | 64.1k |
| sparkarena/Minimax-M3-v0-NVFP4 | quantized | NVFP4 | 242B | XXL | other | sparkarena | 15 | 47.9k |
| olka-fi/MiniMax-M3-MXFP4 | quantized | MXFP4 | 234B | XXL | other | olka-fi | 6 | 42.3k |
| bartowski/MiniMax-M3-GGUF | quantized | GGUF | — | — | other | bartowski | 9 | 39.6k |
| Mapika/MiniMax-M3-NVFP4 | quantized | NVFP4 | 245B | XXL | other | Mapika | 3 | 38.5k |
| lukealonso/MiniMax-M3-NVFP4 | quantized | NVFP4 | 220B | XXL | — | lukealonso | 23 | 17.5k |
| brandonmusic/MiniMax-M3-NVFP4 | quantized | NVFP4 | 246B | XXL | mit | brandonmusic | 10 | 16.4k |
| amd/MiniMax-M3-MXFP4-AttnFP8 | quantized | MXFP4 | 232B | XXL | other | amd | 1 | 15.9k |
| mlx-community/MiniMax-M3-4bit | quantized | -4bit | 427B | XXL | other | mlx-community | 7 | 11.9k |
| Model-SafeTensors/MiniMax-M3-MoE-FP8-128x128 | quantized | -FP8 | 427B | XXL | other | Model-SafeTensors | 0 | 12k |
| nvidia/MiniMax-M3-DSpark | finetune | — | 3.29B | M | other | nvidia | 18 | 9k |
| kaitchup/MiniMax-M3-GGUF-MoQ | quantized | GGUF | — | — | other | kaitchup | 18 | 8.2k |
| spectator2026/MiniMax-M3-AWQ-int4 | quantized | AWQ | 68.8B | XL | other | spectator2026 | 6 | 8.3k |
| Sebesky/MiniMax-M3-W4A16-GPTQ | quantized | -W4A16 | 430B | XXL | other | Sebesky | 4 | 7.1k |
| AesSedai/MiniMax-M3-GGUF | quantized | GGUF | — | — | — | AesSedai | 19 | 5.3k |
| DevQuasar/MiniMaxAI.MiniMax-M3-GGUF | quantized | GGUF | — | — | — | DevQuasar | 1 | 5.4k |
| Sciguy429/MiniMax-M3-MSA-GGUF | quantized | GGUF | — | — | — | Sciguy429 | 2 | 4.9k |
| bullerwins/MiniMax-M3-4bit-W4A16-v0 | quantized | -4bit | 60.1B | XL | other | bullerwins | 1 | 4.7k |
| ressl/MiniMax-M3-uncensored | finetune | — | 427B | XXL | other | ressl | 38 | 2.2k |
| pipenetwork/MiniMax-M3-MLX-mixed-3_6bit | quantized | MLX | 426B | XXL | other | pipenetwork | 2 | 3.6k |
| inferencerlabs/MiniMax-M3-MLX-Q8 | quantized | MLX | — | — | — | inferencerlabs | 3 | 3.5k |
| OsaurusAI/MiniMax-M3-Coder-Small | finetune | — | 240B | XXL | other | OsaurusAI | 6 | 3.4k |
| pipenetwork/MiniMax-M3-MLX-8bit | quantized | MLX | 426B | XXL | other | pipenetwork | 1 | 3.2k |
| unigilby/MiniMax-M3-oQ4 | quantized | — | 427B | XXL | other | unigilby | 2 | 2.6k |
| pipenetwork/MiniMax-M3-MLX-6bit | quantized | MLX | 426B | XXL | other | pipenetwork | 1 | 2.5k |
| thetom-ai/MiniMax-M3-ConfigI-MLX | quantized | MLX | 427B | XXL | other | thetom-ai | 0 | 2.5k |
| pipenetwork/MiniMax-M3-MLX-3bit | quantized | MLX | 426B | XXL | other | pipenetwork | 0 | 2.5k |
| pipenetwork/MiniMax-M3-MLX-4bit | quantized | MLX | 426B | XXL | other | pipenetwork | 1 | 2.3k |
| reduxv1/MiniMax-M3-GGUF | quantized | GGUF | — | — | other | reduxv1 | 1 | 2k |
| avlp12/MiniMax-M3-Alis-MLX-Dynamic | quantized | MLX | 427B | XXL | other | avlp12 | 0 | 2k |
| gghfexp/MiniMax-M3-IQ2_KT-experimental | quantized | GGUF | — | — | — | gghfexp | 4 | 1.7k |
| aquaman164/MiniMax-M3-AutoRound-3.2bit-longctx | quantized | — | 49.6B | XL | other | aquaman164 | 0 | 1.5k |
| Serpen/Minimax-M3-MSA-GGUF | quantized | GGUF | — | — | — | Serpen | 1 | 1.5k |
| OpenYourMind/Minimax-M3-abliterated-clean | finetune | — | 427B | XXL | other | OpenYourMind | 11 | 851 |
| unsloth/MiniMax-M3 | finetune | — | 427B | XXL | other | unsloth | 9 | 894 |
| Date | Commit | SHA |
|---|---|---|
| 2026-07-23 | Add LHTB (Long-Horizon-Terminal-Bench) eval result (#24) | f0e1c1e |
| 2026-07-23 | Update README.md | 77aa6d3 |
| 2026-07-23 | Update README.md | ddf9995 |
| 2026-07-23 | Update README.md | 4db0b31 |
| 2026-07-11 | Update README.md | 5094273 |
| 2026-07-01 | Update README.md | fa68495 |
| 2026-06-23 | Fix YC-Bench score: use full value 2100000 instead of 2.1 (#18) | bfd6c97 |
| 2026-06-23 | Add evaluation results from model card benchmark graph (#17) | cc0e7f5 |
| 2026-06-22 | Update README.md | b1c79b9 |
| 2026-06-22 | Update README.md | ca22f9a |
| 2026-06-16 | Update README.md (#12) | 051e8f9 |
| 2026-06-15 | Update README.md | b868271 |
| 2026-06-13 | Update README.md | 81b23f9 |
| 2026-06-12 | Initial commit | 3a41b31 |
Hosted endpoints observed for MiniMax-M3, sorted by input price (USD per million tokens). Each row names its observer and date; prices change daily, so check the source before quoting. Cheapest observed input price: $0.22/M.
| Provider | Model ref | Context | Quant | $/M in | $/M out | tok/s | TTFT | Tools | Status | Observed |
|---|---|---|---|---|---|---|---|---|---|---|
| DeepInfra deepinfra, openrouter | MiniMaxAI/MiniMax-M3 | 512K | fp8 | $0.22 | $0.88 | — | — | yes | live | 2026-10-24 |
| CoreWeave openrouter | minimax/minimax-m3 | 256K | fp4 | $0.23 | $0.96 | — | — | yes | live | 2026-10-24 |
| GMICloud openrouter | minimax/minimax-m3 | 1M | fp8 | $0.24 | $0.96 | — | — | yes | live | 2026-10-24 |
| Novita hf, openrouter | minimax/minimax-m3 | 977K | fp8 | $0.30 | $1.20 | 49.9 | 1391 ms | yes | live | 2026-10-25 |
| Together AI hf, openrouter | MiniMaxAI/MiniMax-M3 | 512K | unknown | $0.30 | $1.20 | 51.8 | 336 ms | yes | live | 2026-10-25 |
| Fireworks AI hf | accounts/fireworks/models/minimax-m3 | 500K | — | $0.30 | $1.20 | 105.6 | 574 ms | yes | live | 2026-10-25 |
| Parasail parasail, openrouter | parasail-minimax-m3 | 1M | fp8 | $0.30 | $1.20 | — | — | yes | serverless | 2026-10-24 |
| StreamLake openrouter | minimax/minimax-m3 | 977K | fp8 | $0.30 | $1.20 | — | — | yes | live | 2026-10-24 |
| Venice openrouter | minimax/minimax-m3 | 512K | fp8 | $0.30 | $1.20 | — | — | yes | status -5 | 2026-10-24 |
| AtlasCloud openrouter | minimax/minimax-m3 | 512K | fp8 | $0.30 | $1.20 | — | — | yes | live | 2026-10-24 |
| Minimax openrouter | minimax/minimax-m3 | 512K | fp8 | $0.30 | $1.20 | — | — | yes | live | 2026-10-24 |
| ModelRun openrouter | minimax/minimax-m3 | 1M | fp8 | $0.30 | $1.30 | — | — | yes | live | 2026-10-24 |
| Mara openrouter | minimax/minimax-m3 | 1M | unknown | $0.60 | $2.40 | — | — | yes | status -5 | 2026-10-24 |
| Featherless hf | MiniMaxAI/MiniMax-M3 | — | — | — | — | — | — | — | live | 2026-10-25 |
Ranked by source signals (HN, Lobsters, authority domains, official posts) and recency. Summaries are generated from a stored copy of the article text; every sentence cites a span of that text, and nothing is shown that failed the citation check.
arXiv links found in the model card and its tags. "Peer-reviewed" is shown only with evidence: a published venue in OpenAlex (measured) or the authors' own journal reference on arXiv (reported).
Hub snapshot: 2026-10-25 · HF API: 2026-10-24 21:31 UTC · Providers: 2026-10-24 21:44 UTC · Articles: 2026-10-24 21:45 UTC · Summary: 2026-10-07 14:59 UTC · Last verified 2026-10-25
Email alerts are not open yet; the feeds above are the same data. See feeds for the item schema.